Models#
Qibo provides models for both the circuit based and the adiabatic quantum
computation paradigms. Circuit based models include Circuit models which
allow defining arbitrary circuits and the quantum algorithms of Algorithms,
such as the Quantum Fourier Transform (qibo.models.QFT).
Adiabatic quantum computation is simulated using the Time evolution
of state vectors.
In order to perform calculations and apply gates to a state vector a backend
has to be used. The backends are defined in qibo/backends.
Circuit and gate objects are backend independent and can be executed with
any of the available backends.
Qibo uses big-endian byte order, which means that the most significant qubit is the one with index 0, while the least significant qubit is the one with the highest index.
Circuit models#
Circuit#
- class qibo.models.circuit.Circuit(nqubits=None, accelerators=None, density_matrix=False, wire_names=None)[source]#
Circuit object which holds a list of gates.
This circuit is symbolic and cannot perform calculations. A specific backend has to be used for performing calculations.
Circuits can be created with a specific number of qubits and wire names.
Either
nqubitsorwire_namesmust be provided.If only
nqubitsis provided, wire names will default to[0, 1, ..., nqubits - 1].If only
wire_namesis provided,nqubitswill be set to the length ofwire_names.nqubitsandwire_namesmust be consistent with each other.
Example:
from qibo import Circuit

# Every circuit initialization below is valid
circuit = Circuit(5)  # Default wire names are [0, 1, 2, 3, 4]
circuit = Circuit(["A", "B", "C", "D", "E"])
circuit = Circuit(5, wire_names=["A", "B", "C", "D", "E"])
circuit = Circuit(wire_names=["A", "B", "C", "D", "E"])
- Parameters:
- init_kwargs#
a dictionary with the following keys
nqubits
accelerators
density_matrix
wire_names.
- Type:
- queue#
List that holds the queue of gates of a circuit.
- Type:
_Queue
- parametrized_gates#
List of parametric gates.
- Type:
_ParametrizedGates
- trainable_gates#
List of trainable gates.
- Type:
_ParametrizedGates
- _final_state#
Final result after full simulation of the circuit.
- compiled#
Circuit executor. Defaults to
None.- Type:
CompiledExecutor
- repeated_execution#
If True, the circuit would be re-executed when sampling. Defaults to
False.- Type:
- density_matrix#
If True, the circuit would evolve density matrices. If
False, defaults to statevector simulation. Defaults toFalse.- Type:
bool, optional
- accelerators#
Dictionary that maps device names to the number of times each device will be used. Defaults to
None.- Type:
dict, optional
- queues#
Gate queues for each accelerator device. Defaults to
None.- Type:
DistributedQueues
- on_qubits(*qubits)[source]#
Creates a new
Circuitwith the gates of the circuit acting on specified qubits.Useful for adding a circuit as a subroutine in a larger circuit. The returned circuit has as many qubits as needed to contain the gates, i.e. the largest of
qubitsplus one, and it can be iterated over to retrieve its gates.- Parameters:
qubits (int) – Qubit ids that the gates should act.
- Returns:
circuit with the gates acting on
qubits.- Return type:
Example
from qibo import Circuit, gates

# create small circuit on 4 qubits
small_circuit = Circuit(4)
small_circuit.add(gates.RX(qubit, theta=0.1) for qubit in range(4))
small_circuit.add((gates.CNOT(0, 1), gates.CNOT(2, 3)))
# create large circuit on 8 qubits
large_circuit = Circuit(8)
large_circuit.add(gates.RY(qubit, theta=0.1) for qubit in range(8))
# add the small circuit to the even qubits of the large one
large_circuit.add(small_circuit.on_qubits(*range(0, 8, 2)))
- light_cone(*qubits)[source]#
Reduces circuit to the qubits relevant for an observable.
Useful for calculating expectation values of local observables without requiring simulation of large circuits. Uses the light cone construction described in issue #571.
- Parameters:
qubits (int) – Qubit ids that the observable has support on.
- Returns:
- Circuit that contains only
the qubits that are required for calculating expectation involving the given observable qubits.
- qubit_map (dict): Dictionary mapping the qubit ids of the original
circuit to the ids in the new one.
- Return type:
circuit (
qibo.models.Circuit)
- controlled_by(*qubits)[source]#
Creates a new
Circuitin which every gate is controlled by the givenqubits.The original circuit is not modified. The control qubits cannot be targets (or controls) of any of the gates of the circuit, but they do not need to belong to it. In particular, a small circuit can be controlled by qubits of a larger circuit it will be added to, e.g.
large_circuit.add(small_circuit.controlled_by(5)). If some ofqubitsis not smaller than the number of qubits of the original circuit, the new circuit has as many qubits as needed to contain it, andwire_namesare not kept. Gates that act as the identity, i.e.qibo.gates.I,qibo.gates.Alignandqibo.gates.Barrier, are kept uncontrolled. The remaining gates are controlled according to the rules ofqibo.gates.Gate.controlled_by().Note
Gates that are already controlled, e.g.
qibo.gates.CNOT, are rebuilt from their uncontrolled counterpart, e.g.qibo.gates.X, so thatqubitsare added to their original controls. This is not possible forqibo.gates.DEUTSCHandqibo.gates.FanOut, for which aNotImplementedErroris raised. Measurements and noise channels cannot be controlled either.- Parameters:
*qubits (int) – ids of the qubits that control the circuit.
- Returns:
circuit controlled by
qubits.- Return type:
Example
from qibo import Circuit, gates

# subroutine acting on qubits 0 and 1
small_circuit = Circuit(2)
small_circuit.add(gates.H(0))
small_circuit.add(gates.CNOT(0, 1))

# add the subroutine to a larger circuit, controlled by its qubit 2
large_circuit = Circuit(4)
large_circuit.add(gates.H(2))
large_circuit.add(small_circuit.controlled_by(2))

# the same, with the subroutine acting on qubits 1 and 3
large_circuit.add(small_circuit.on_qubits(1, 3).controlled_by(0))
- copy(deep=False)[source]#
Creates a copy of the current
circuitas a newCircuitmodel.- Parameters:
deep (bool) – If
Truecopies of the gate objects will be created for the new circuit. IfFalse, the same gate objects ofcircuitwill be used.- Returns:
The copied circuit object.
- invert()[source]#
Creates a new
Circuitthat is the inverse of the original.Inversion is obtained by taking the dagger of all gates in reverse order. If the original circuit contains parametrized gates, dagger will change their parameters. This action is not persistent, so if the parameters are updated afterwards, for example using
qibo.models.circuit.Circuit.set_parameters(), the action of dagger will be overwritten. If the original circuit contains measurement gates, these are included in the inverted circuit.- Returns:
Circuit corresponding to the inverse of the original
circuit.- Return type:
qibo.models.Circuit
- decompose(*free, method='standard', **kwargs)[source]#
Decomposes circuit’s gates to gates supported by OpenQASM.
- Parameters:
free (int) – Ids of free (work) qubits that can be used as dirty auxiliary qubits in the decomposition of multi-controlled gates, that is, they can be in any state and are left unchanged. They must not be qubits that the decomposed gates act on.
method (str, optional) – Choice of gate set for the decomposition. If
"standard", decomposes circuit intoqibo.gates.gates.CNOT,qibo.gates.gates.RX,qibo.gates.gates.RY,qibo.gates.gates.RZ,qibo.gates.gates.U1,qibo.gates.gates.U2,qibo.gates.gates.U3, and Clifford gates. If"clifford_plus_t", decomposes the circuit intoqibo.gates.gates.CNOT,qibo.gates.gates.H,qibo.gates.gates.S,qibo.gates.gates.X,qibo.gates.gates.Y,qibo.gates.gates.Z, andqibo.gates.gates.T. Defaults to"standard".kwargs (dict, optional) – Additional arguments passed to
qibo.gates.abstract.Gate.decompose()for each gate. For example,clean,minimize_toffolisandminimize_depthselect other decompositions of multi-controlled gates.
- Returns:
Circuit that contains only gates that are supported by OpenQASM and has the same effect as the original circuit. The decompositions that are equal to the gate only up to a global phase end with a
qibo.gates.GlobalPhasegate that corrects them. All of them are added modulo \(2 \pi\) into a singleqibo.gates.GlobalPhasegate that is the last gate of the circuit, and which is not trainable and is not added if the total phase is zero, seeqibo.models.circuit.Circuit.global_phase.- Return type:
- with_pauli_noise(noise_map)[source]#
Creates a copy of the circuit with Pauli noise gates after each gate.
If the original circuit uses state vectors then noise simulation will be done using sampling and repeated circuit execution. In order to use density matrices the original circuit should be created setting the flag
density_matrix=True. For more information we refer to the How to perform noisy simulation? example.- Parameters:
noise_map (dict) – list of tuples \((P_{k}, p_{k})\), where \(P_{k}\) is a
strrepresenting the \(k\)-th \(n\)-qubit Pauli operator, and \(p_{k}\) is the associated probability.- Returns:
Circuit object that contains all the gates of the original circuit and additional noise channels on all qubits after every gate.
Example
from qibo import Circuit, gates
# use density matrices for noise simulation
circuit = Circuit(2, density_matrix=True)
circuit.add([gates.H(0), gates.H(1), gates.CNOT(0, 1)])
noise_map = {
    0: list(zip(["X", "Z"], [0.1, 0.2])),
    1: list(zip(["Y", "Z"], [0.2, 0.1]))
}
noisy_circuit = circuit.with_pauli_noise(noise_map)
# ``noisy_circuit`` will be equivalent to the following circuit
circuit_2 = Circuit(2, density_matrix=True)
circuit_2.add(gates.H(0))
circuit_2.add(gates.PauliNoiseChannel(0, [("X", 0.1), ("Z", 0.2)]))
circuit_2.add(gates.H(1))
circuit_2.add(gates.PauliNoiseChannel(1, [("Y", 0.2), ("Z", 0.1)]))
circuit_2.add(gates.CNOT(0, 1))
circuit_2.add(gates.PauliNoiseChannel(0, [("X", 0.1), ("Z", 0.2)]))
circuit_2.add(gates.PauliNoiseChannel(1, [("Y", 0.2), ("Z", 0.1)]))
- add(gate)[source]#
Add a gate to a given queue.
- Parameters:
gate (
qibo.gates.Gate) – the gate object to add. See Gates for a list of available gates. gate can also be an iterable or generator of gates. In this case all gates in the iterable will be added in the circuit.- Returns:
If the circuit contains measurement gates with
collapse=Trueasympy.Symbolthat parametrizes the corresponding outcome.
- gates_of_type(gate)[source]#
Finds all gate objects of specific type or name.
This method can be affected by how
qibo.gates.Gate.controlled_by()behaves with certain gates. To see howqibo.gates.Gate.controlled_by()affects gates, we refer to the documentation ofqibo.gates.Gate.controlled_by().
- property global_phase: float#
Global phase \(\theta\) of the circuit, in radians.
It is the sum of the phases of all
qibo.gates.GlobalPhasegates of the circuit, so that the unitary of the circuit contains the global factor \(e^{i \theta}\). It is \(0\) unless the circuit has such gates. In particular, the circuits thatqibo.models.circuit.Circuit.decompose()and the transpiler return have a singleqibo.gates.GlobalPhasegate at their end, if the decomposition of some of their gates is equal to the gate only up to a global phase, which the decomposition compensates for.Note
The phase is only defined modulo \(2 \pi\), and the property is not reduced: it is the plain sum of the parameters of the gates, which can be outside the interval \([0, 2\pi)\) if the circuit has several global phase gates. The circuits that
qibo.models.circuit.Circuit.decompose()and the transpiler return have it in \([0, 2\pi)\), since they add the phases modulo \(2 \pi\), andqibo.models.circuit.Circuit.draw()always reduces it to that interval.
- set_parameters(parameters)[source]#
Updates the parameters of the circuit’s parametrized gates.
For more information on how to use this method we refer to the How to use parametrized gates? example.
- Parameters:
parameters (list[float] | dict[str, float] | ArrayLike) – Container holding the new parameter values. It can have one of the following types: List with length equal to the number of parametrized gates and each of its elements compatible with the corresponding gate. Dictionary with keys that are references to the parametrized gates and values that correspond to the new parameters for each gate. Flat list with length equal to the total number of free parameters in the circuit. A backend supported tensor (for example
np.ndarrayortf.Tensor) may also be given instead of a flat list.- Return type:
None
Example
from qibo import Circuit, gates
# create a circuit with all parameters set to 0.
circuit = Circuit(3)
circuit.add(gates.RX(0, theta=0))
circuit.add(gates.RY(1, theta=0))
circuit.add(gates.CZ(1, 2))
circuit.add(gates.fSim(0, 2, theta=0, phi=0))
circuit.add(gates.H(2))

# set new values to the circuit's parameters using list
params = [0.123, 0.456, (0.789, 0.321)]
circuit.set_parameters(params)
# or using dictionary
params = {
    circuit.queue[0]: 0.123,
    circuit.queue[1]: 0.456,
    circuit.queue[3]: (0.789, 0.321)
}
circuit.set_parameters(params)
# or using flat list (or an equivalent `np.array`/`tf.Tensor`/`torch.Tensor`)
params = [0.123, 0.456, 0.789, 0.321]
circuit.set_parameters(params)
- get_parameters(output_format='list', include_not_trainable=False)[source]#
Returns the parameters of all parametrized gates in the circuit.
Inverse method of
qibo.models.circuit.Circuit.set_parameters().- Parameters:
output_format (str) – Format to return the variational parameters. Available formats are
"list","dict"and"flatlist". Seeqibo.models.circuit.Circuit.set_parameters()for more details on each format. Default is"list".include_not_trainable (bool) – If
Trueit includes the parameters of non-trainable parametrized gates in the returned list or dictionary. Default isFalse.
- Return type:
- associate_gates_with_parameters()[source]#
Associates to each parameter its gate.
- Returns:
A nparams-long flatlist whose i-th element is the gate parameterized by the i-th parameter.
- Return type:
list[qibo.gates.abstract.Gate]
- summary()[source]#
Display a summary of the circuit.
The summary contains the circuit depths, total number of qubits and the all gates sorted in decreasing number of appearance.
Example:
from qibo import Circuit, gates

circuit = Circuit(3)
circuit.add(gates.H(0))
circuit.add(gates.H(1))
circuit.add(gates.CNOT(0, 2))
circuit.add(gates.CNOT(1, 2))
circuit.add(gates.H(2))
circuit.add(gates.TOFFOLI(0, 1, 2))

circuit.summary()

# Output:
# Circuit depth = 5
# Total number of gates = 6
# Number of qubits = 3
# Most common gates:
# h: 3
# cx: 2
# ccx: 1
- Return type:
None
- fuse(max_qubits=2)[source]#
Creates an equivalent circuit by fusing gates for increased simulation performance.
- Parameters:
max_qubits (int) – Maximum number of qubits in the fused gates.
- Returns:
A
qibo.core.circuit.Circuitobject containingqibo.gates.FusedGategates, each of which corresponds to a group of some original gates. For more details on the fusion algorithm we refer to the Circuit fusion section.
Example
from qibo import Circuit, gates

circuit = Circuit(2)
circuit.add([gates.H(0), gates.H(1)])
circuit.add(gates.CNOT(0, 1))
circuit.add([gates.Y(0), gates.Y(1)])
# create circuit with fused gates
fused_circuit = circuit.fuse()
# now ``fused_circuit`` contains a single ``FusedGate`` that is
# equivalent to applying the five original gates
- unitary(backend=None)[source]#
Creates the unitary matrix corresponding to all circuit gates.
This is a \(2^{n} \times 2^{n}`\) matrix obtained by multiplying all circuit gates, where \(n\) is
nqubits.- Parameters:
backend (Backend | None) –
- Return type:
ArrayLike
- property final_state: ArrayLike#
Returns the final state after full simulation of the circuit.
If the circuit is executed more than once, only the last final state is returned.
- execute(initial_state=None, nshots=1000, **kwargs)[source]#
Executes the circuit. Exact implementation depends on the backend.
- Parameters:
initial_state (ndarray or
qibo.models.circuit.Circuit) – Initial configuration. It can be specified by the setting the state vector using an array or a circuit. IfNone, the initial state is|000..00>.nshots (int, optional) – Number of shots. Defaults ot \(1000\).
- Returns:
Either a
qibo.result.QuantumState,qibo.result.MeasurementOutcomesorqibo.result.CircuitResultdepending on the circuit’s configuration.
- property raw: dict#
Serialize the circuit to a JSON-compatible dictionary.
This is a thin wrapper over
qibo.gates.Gate.raw(). The returned dictionary has the following structure:{ "queue": [ <gate.raw>, ... ], # list of serialized gates "nqubits": int, # number of qubits "density_matrix": bool, # whether a density matrix is used "wire_names": list | None, # wire names (or None) "qibo_version": str, # qibo version used for serialization }Each entry of
queueis the output ofqibo.gates.Gate.raw(). The dictionary can be loaded back into a circuit withqibo.models.circuit.Circuit.from_dict().- Returns:
JSON-compatible representation of the circuit.
- Return type:
- classmethod from_dict(raw)[source]#
Load from serialization.
Essentially the counter-part of
raw().- Parameters:
raw (dict) –
- to_qasm(extended_compatibility=False)[source]#
Convert circuit to a QASM string.
- Parameters:
extended_compatibility (bool) – if
True, unrolls more exotic gates in their decomposition by defining them as custom gates, this increases the compatibility with other frameworks, such asqiskit. Defaults toFalse.- Returns:
The generated QASM.
- Return type:
Note
This method does not support multi-controlled gates and gates with
torch.Tensoras parameters. Theqibo.gates.GlobalPhasegates are not exported, because OpenQASM 2 cannot represent them. A warning is logged if the global phase of the circuit is not zero.
- to_qasm_file(qasm_file, extended_compatibility=False)[source]#
_summary_
- Parameters:
- Return type:
None
- classmethod from_qasm(qasm_code, **circuit_kwargs)[source]#
Constructs a circuit from QASM code.
- Parameters:
- Returns:
Circuit containing the gates specified by the given QASM script.
- Return type:
Example
from qibo import Circuit, gates
qasm_code = '''OPENQASM 2.0;
include "qelib1.inc";
qreg q[2];
h q[0];
h q[1];
cx q[0],q[1];'''
circuit = Circuit.from_qasm(qasm_code)
# is equivalent to creating the following circuit
circuit_2 = Circuit(2)
circuit_2.add(gates.H(0))
circuit_2.add(gates.H(1))
circuit_2.add(gates.CNOT(0, 1))
- classmethod from_qasm_file(qasm_file, **circuit_kwargs)[source]#
Constructs a circuit from QASM code in a
qasm_file.- Parameters:
- Returns:
Circuit containing the gates specified by the given QASM script.
- Return type:
- to_qir()[source]#
Convert circuit to QIR circuit.
Uses qbraid (https://github.com/qBraid/qBraid) to transpile the circuit into pyqir circuits.
- to_cudaq()[source]#
Convert circuit to CUDA-Q (quake) code.
Uses qbraid (https://github.com/qBraid/qBraid) to transpile the circuit into cudaq circuits.
- classmethod from_cudaq(cudaq_circuit_code)[source]#
Construct a circuit from CUDA-Q (quake) code.
Uses qbraid (https://github.com/qBraid/qBraid) to transpile the cudaq circuit into a qibo.models.circuit.Circuit.
- Parameters:
cudaq_circuit_code (PyKernel) – kernel containing the cudaq circuit code.
- Returns:
qibo.models.circuit.Circuitrepresenting the given circuit.
- diagram(line_wrap=100, legend=False, parallel=False)[source]#
Build the string representation of the circuit diagram.
If the circuit has a global phase different from zero, see
qibo.models.circuit.Circuit.global_phase, it is written above the diagram since it acts on no wire. It is reduced to the interval \([0, 2\pi)\) and written as a fraction of \(\pi\), such as3π/4, or as a decimal multiple of \(\pi\) if it is not a fraction with a small denominator.See
qibo.models.circuit.Circuit.draw()for the arguments.
- draw(line_wrap=100, legend=False, parallel=False)[source]#
Draw text circuit using unicode symbols.
The
qibo.models.circuit.Circuit.global_phaseof the circuit is written above the diagram, as a fraction of \(\pi\) whenever possible, if it is different from zero.- Parameters:
line_wrap (int, optional) – maximum number of characters per line. This option split the circuit text diagram in chunks of line_wrap characters. Defaults to \(100\).
legend (bool, optional) – If
Trueprints a legend below the circuit for callbacks and channels. Defaults toFalse.parallel (bool, optional) – If
True, multi-qubit gates acting on disjoint sets of wires are drawn in the same column, as single-qubit gates already are. A gate occupies every wire between its outermost qubits, so gates whose vertical connectors would cross are still drawn in separate columns. IfFalse, each multi-qubit gate is drawn in its own column. Defaults toFalse.
- Return type:
None
Circuit addition#
qibo.models.circuit.Circuit objects support addition. For example
circuit_1 = QFT(4)

circuit_2 = Circuit(4)
circuit_2.add(gates.RZ(0, 0.1234))
circuit_2.add(gates.RZ(1, 0.1234))
circuit_2.add(gates.RZ(2, 0.1234))
circuit_2.add(gates.RZ(3, 0.1234))

circuit = circuit_1 + circuit_2
will create a circuit that performs the Quantum Fourier Transform on four qubits followed by Rotation-Z gates.
Circuit fusion#
Gates in a circuit can be fused into a smaller number of
qibo.gates.special.FusedGate objects using
qibo.models.circuit.Circuit.fuse(). See Circuit fusion
for a detailed description of the fusion algorithm and worked examples.
Variational models#
Variational Quantum Eigensolver (VQE)#
- class qibo.models.variational.VQE(circuit, hamiltonian)[source]#
This class implements the variational quantum eigensolver algorithm.
- Parameters:
circuit (
qibo.models.circuit.Circuit) – Circuit that implements the variaional ansatz.hamiltonian (
qibo.hamiltonians.Hamiltonian) – Hamiltonian object.
Example
import numpy as np

from qibo import Circuit, gates
from qibo.hamiltonians import XXZ
from qibo.models import VQE

# create circuit ansatz for two qubits
circuit = Circuit(2)
circuit.add(gates.RY(0, theta=0))
# create XXZ Hamiltonian for two qubits
hamiltonian = XXZ(2)
# create VQE model for the circuit and Hamiltonian
vqe = VQE(circuit, hamiltonian)
# optimize using random initial variational parameters
initial_parameters = np.random.uniform(0, 2, 1)
vqe.minimize(initial_parameters)
- minimize(initial_state, method='Powell', loss_func=None, jac=None, hess=None, hessp=None, bounds=None, constraints=(), tol=None, callback=None, options=None, compile=False, processes=None)[source]#
Search for parameters which minimizes the hamiltonian expectation.
- Parameters:
initial_state (array) – a initial guess for the parameters of the variational circuit.
method (str) – the desired minimization method. See
qibo.optimizers.optimize()for available optimization methods.loss (callable) – loss function, the default one is
qibo.models.utils.vqe_loss().jac (dict) – Method for computing the gradient vector for scipy optimizers.
hess (dict) – Method for computing the hessian matrix for scipy optimizers.
hessp (callable) – Hessian of objective function times an arbitrary vector for scipy optimizers.
bounds (sequence or Bounds) – Bounds on variables for scipy optimizers.
constraints (dict) – Constraints definition for scipy optimizers.
tol (float) – Tolerance of termination for scipy optimizers.
callback (callable) – Called after each iteration for scipy optimizers.
options (dict) – a dictionary with options for the different optimizers.
compile (bool) – whether the TensorFlow graph should be compiled.
processes (int) – number of processes when using the paralle BFGS method.
- Returns:
The final expectation value. The corresponding best parameters. The optimization result object. For scipy methods it returns the
OptimizeResult, for'cma'theCMAEvolutionStrategy.result, and for'sgd'the options used during the optimization.
Adiabatically-assisted Variational Quantum Eigensolver (AAVQE)#
- class qibo.models.variational.AAVQE(circuit, easy_hamiltonian, problem_hamiltonian, s, nsteps=10, t_max=1, bounds_tolerance=1e-07, time_tolerance=1e-07)[source]#
This class implements the Adiabatically Assisted Variational Quantum Eigensolver algorithm. See https://arxiv.org/abs/1806.02287.
- Parameters:
circuit (
qibo.models.circuit.Circuit) – variational ansatz.easy_hamiltonian (
qibo.hamiltonians.Hamiltonian) – initial Hamiltonian object.problem_hamiltonian (
qibo.hamiltonians.Hamiltonian) – problem Hamiltonian object.s (callable) – scheduling function of time that defines the adiabatic evolution. It must verify boundary conditions: s(0) = 0 and s(1) = 1.
nsteps (float) – number of steps of the adiabatic evolution.
t_max (float) – total time evolution.
bounds_tolerance (float) – tolerance for checking s(0) = 0 and s(1) = 1.
time_tolerance (float) – tolerance for checking if time is greater than t_max.
Example
import numpy as np

from qibo import Circuit, gates
from qibo.hamiltonians import X, XXZ
from qibo.models import AAVQE

# create circuit ansatz for two qubits
circuit = Circuit(2)
circuit.add(gates.RY(0, theta=0))
circuit.add(gates.RY(1, theta=0))
# define the easy and the problem Hamiltonians.
easy_hamiltonian = X(2)
problem_hamiltonian = XXZ(2)
# define a scheduling function with only one parameter
# and boundary conditions s(0) = 0, s(1) = 1
s = lambda t: t
# create AAVQE model
aavqe = AAVQE(
    circuit,
    easy_hamiltonian,
    problem_hamiltonian,
    s,
    nsteps=10,
    t_max=1
)
# optimize using random initial variational parameters
np.random.seed(0)
initial_parameters = np.random.uniform(0, 2*np.pi, 2)
ground_energy, params = aavqe.minimize(initial_parameters)
- minimize(params, method='BFGS', jac=None, hess=None, hessp=None, bounds=None, constraints=(), tol=None, options=None, compile=False, processes=None)[source]#
Performs minimization to find the ground state of the problem Hamiltonian.
- Parameters:
params (np.ndarray or list) – initial guess for the parameters of the variational circuit.
method (str) – optimizer to employ.
jac (dict) – Method for computing the gradient vector for scipy optimizers.
hess (dict) – Method for computing the hessian matrix for scipy optimizers.
hessp (callable) – Hessian of objective function times an arbitrary vector for scipy optimizers.
bounds (sequence or Bounds) – Bounds on variables for scipy optimizers.
constraints (dict) – Constraints definition for scipy optimizers.
tol (float) – Tolerance of termination for scipy optimizers.
options (dict) – a dictionary with options for the different optimizers.
compile (bool) – whether the TensorFlow graph should be compiled.
processes (int) – number of processes when using the parallel BFGS method.
Quantum Approximate Optimization Algorithm (QAOA)#
- class qibo.models.variational.QAOA(hamiltonian, mixer=None, solver='exp', callbacks=None, accelerators=None)[source]#
Quantum Approximate Optimization Algorithm (QAOA) model.
The QAOA is introduced in arXiv:1411.4028.
- Parameters:
hamiltonian (
qibo.hamiltonians.Hamiltonian) – problem Hamiltonian whose ground state is sought.mixer (
qibo.hamiltonians.Hamiltonian) – mixer Hamiltonian. Must be of the same type and act on the same number of qubits ashamiltonian. IfNone,qibo.hamiltonians.Xis used.solver (str) – solver used to apply the exponential operators. Default solver is ‘exp’ (
qibo.solvers.Exponential).callbacks (list) – List of callbacks to calculate during evolution.
accelerators (dict) – Dictionary of devices to use for distributed execution. This option is available only when
hamiltonianis aqibo.hamiltonians.SymbolicHamiltonian.
Example
import numpy as np

from qibo.hamiltonians import XXZ
from qibo.models import QAOA

# create XXZ Hamiltonian for four qubits
hamiltonian = XXZ(4)
# create QAOA model for this Hamiltonian
qaoa = QAOA(hamiltonian)
# optimize using random initial variational parameters
# and default options and initial state
initial_parameters = 0.01 * np.random.random(4)
best_energy, final_parameters, extra = qaoa.minimize(initial_parameters, method="BFGS")
- set_parameters(p)[source]#
Sets the variational parameters.
- Parameters:
p (np.ndarray) – 1D-array holding the new values for the variational parameters. Length should be an even number.
- execute(initial_state=None)[source]#
Applies the QAOA exponential operators to a state.
- Parameters:
initial_state (np.ndarray) – Initial state vector.
- Returns:
State vector after applying the QAOA exponential gates.
- minimize(initial_p, initial_state=None, method='Powell', loss_func=None, loss_func_param=None, jac=None, hess=None, hessp=None, bounds=None, constraints=(), tol=None, callback=None, options=None, compile=False, processes=None)[source]#
Optimizes the variational parameters of the QAOA. A few loss functions are provided for QAOA optimizations such as expected value (default), CVar which is introduced in Quantum 4, 256, and Gibbs loss function which is introduced in PRR 2, 023074 (2020).
- Parameters:
initial_p (np.ndarray) – initial guess for the parameters.
initial_state (np.ndarray) – initial state vector of the QAOA.
method (str) – the desired minimization method. See
qibo.optimizers.optimize()for available optimization methods.loss_func (function) – the desired loss function. If it is
None, the expectation is used.loss_func_param (dict) – a dictionary to pass in the loss function parameters.
jac (dict) – Method for computing the gradient vector for scipy optimizers.
hess (dict) – Method for computing the hessian matrix for scipy optimizers.
hessp (callable) – Hessian of objective function times an arbitrary vector for scipy optimizers.
bounds (sequence or Bounds) – Bounds on variables for scipy optimizers.
constraints (dict) – Constraints definition for scipy optimizers.
tol (float) – Tolerance of termination for scipy optimizers.
callback (callable) – Called after each iteration for scipy optimizers.
options (dict) – a dictionary with options for the different optimizers.
compile (bool) – whether the TensorFlow graph should be compiled.
processes (int) – number of processes when using the paralle BFGS method.
- Returns:
The final energy (expectation value of the
hamiltonian). The corresponding best parameters. The optimization result object. For scipy methods it returns theOptimizeResult, for'cma'theCMAEvolutionStrategy.result, and for'sgd'the options used during the optimization.
Example
from qibo.hamiltonians import XXZ
from qibo.models import QAOA
from qibo.models.utils import cvar, gibbs

h = XXZ(3)
qaoa = QAOA(h)
initial_p = [0.314, 0.22, 0.05, 0.59]
best, params, _ = qaoa.minimize(initial_p)
best, params, _ = qaoa.minimize(
    initial_p, loss_func=cvar, loss_func_param={'alpha':0.1}
)
best, params, _ = qaoa.minimize(
    initial_p, loss_func=gibbs, loss_func_param={'eta':0.1}
)
Feedback-based Algorithm for Quantum Optimization (FALQON)#
- class qibo.models.variational.FALQON(hamiltonian, mixer=None, solver='exp', callbacks=None, accelerators=None)[source]#
Feedback-based ALgorithm for Quantum OptimizatioN (FALQON) model.
The FALQON is introduced in arXiv:2103.08619. It inherits the QAOA class.
- Parameters:
hamiltonian (
qibo.hamiltonians.Hamiltonian) – problem Hamiltonian whose ground state is sought.mixer (
qibo.hamiltonians.Hamiltonian) – mixer Hamiltonian. IfNone,qibo.hamiltonians.Xis used.solver (str) – solver used to apply the exponential operators. Default solver is ‘exp’ (
qibo.solvers.Exponential).callbacks (list) – List of callbacks to calculate during evolution.
accelerators (dict) – Dictionary of devices to use for distributed execution. This option is available only when
hamiltonianis aqibo.hamiltonians.SymbolicHamiltonian.
Example
import numpy as np

from qibo.hamiltonians import XXZ
from qibo.models import FALQON

# create XXZ Hamiltonian for four qubits
hamiltonian = XXZ(4)
# create FALQON model for this Hamiltonian
falqon = FALQON(hamiltonian)
# optimize using random initial variational parameters
# and default options and initial state
delta_t = 0.01
max_layers = 3
best_energy, final_parameters, extra = falqon.minimize(delta_t, max_layers)
- minimize(delta_t, max_layers, initial_state=None, tol=None, callback=None)[source]#
Optimizes the variational parameters of the FALQON.
- Parameters:
delta_t (float) – initial guess for the time step. A too large delta_t will make the algorithm fail.
max_layers (int) – maximum number of layers allowed for the FALQON.
initial_state (np.ndarray) – initial state vector of the FALQON.
tol (float) – Tolerance of energy change. If not specified, no check is done.
callback (callable) – Called after each iteration for scipy optimizers.
options (dict) – a dictionary with options for the different optimizers.
- Returns:
The final energy (expectation value of the
hamiltonian). The corresponding best parameters. extra: variable with historical data for the energy and callbacks.
Time evolution#
State evolution#
- class qibo.models.evolution.StateEvolution(hamiltonian, dt, solver='exp', callbacks=None, accelerators=None)[source]#
Unitary time evolution of a state vector under a Hamiltonian.
- Parameters:
hamiltonian (
qibo.hamiltonians.abstract.AbstractHamiltonian) – Hamiltonian to evolve under.dt (float) – Time step to use for the numerical integration of Schrondiger’s equation.
solver (str) – Solver to use for integrating Schrodinger’s equation. Available solvers are ‘exp’ which uses the exact unitary evolution operator and ‘rk4’ or ‘rk45’ which use Runge-Kutta methods to integrate the Schordinger’s time-dependent equation in time. When the ‘exp’ solver is used to evolve a
qibo.hamiltonians.hamiltonians.SymbolicHamiltonianthen the Trotter decomposition of the evolution operator will be calculated and used automatically. If the ‘exp’ is used on a denseqibo.core.hamiltonians.hamiltonians.Hamiltonianthe full Hamiltonian matrix will be exponentiated to obtain the exact evolution operator. Runge-Kutta solvers use simple matrix multiplications of the Hamiltonian to the state and no exponentiation is involved.callbacks (list) – List of callbacks to calculate during evolution.
accelerators (dict) – Dictionary of devices to use for distributed execution. This option is available only when the Trotter decomposition is used for the time evolution.
Example
import numpy as np

from qibo.hamiltonians import TFIM
from qibo.models import StateEvolution

# create critical (h=1.0) TFIM Hamiltonian for three qubits
hamiltonian = TFIM(3, h=1.0)
# initialize evolution model with step dt=1e-2
evolve = StateEvolution(hamiltonian, dt=1e-2)
# initialize state to |+++>
initial_state = np.ones(8, dtype=complex) / np.sqrt(8)
# execute evolution for total time T=2
final_state2 = evolve(final_time=2, initial_state=initial_state)
Adiabatic evolution#
- class qibo.models.evolution.AdiabaticEvolution(h0, h1, s, dt, solver='exp', callbacks=None, accelerators=None)[source]#
Adiabatic evolution of a state vector under the following Hamiltonian:
\[H(t) = (1 - s(t)) H_0 + s(t) H_1\]- Parameters:
h0 (
qibo.hamiltonians.abstract.AbstractHamiltonian) – Easy Hamiltonian.h1 (
qibo.hamiltonians.abstract.AbstractHamiltonian) – Problem Hamiltonian. These Hamiltonians should be time-independent.s (callable) – Function of time that defines the scheduling of the adiabatic evolution. Can be either a function of time s(t) or a function with two arguments s(t, p) where p corresponds to a vector of parameters to be optimized.
dt (float) – Time step to use for the numerical integration of Schrondiger’s equation.
solver (str) – Solver to use for integrating Schrodinger’s equation. Available solvers are ‘exp’ which uses the exact unitary evolution operator and ‘rk4’ or ‘rk45’ which use Runge-Kutta methods to integrate the Schordinger’s time-dependent equation in time. When the ‘exp’ solver is used to evolve a
qibo.hamiltonians.hamiltonians.SymbolicHamiltonianthen the Trotter decomposition of the evolution operator will be calculated and used automatically. If the ‘exp’ is used on a denseqibo.hamiltonians.hamiltonians.Hamiltonianthe full Hamiltonian matrix will be exponentiated to obtain the exact evolution operator. Runge-Kutta solvers use simple matrix multiplications of the Hamiltonian to the state and no exponentiation is involved.callbacks (list) – List of callbacks to calculate during evolution.
accelerators (dict) – Dictionary of devices to use for distributed execution. This option is available only when the Trotter decomposition is used for the time evolution.
- property schedule#
Returns scheduling as a function of time.
- execute(final_time, start_time=0.0, initial_state=None)[source]#
Runs unitary evolution for a given total time.
- Parameters:
- Returns:
Final state vector a
tf.Tensoror aqibo.core.distutils.DistributedStatewhen a distributed execution is used.
- minimize(initial_parameters, method='BFGS', options=None, messages=False)[source]#
Optimize the free parameters of the scheduling function.
- Parameters:
initial_parameters (np.ndarray) – Initial guess for the variational parameters that are optimized. The last element of the given array should correspond to the guess for the total evolution time T.
method (str) – The desired minimization method. One of
"cma"(genetic optimizer),"sgd"(gradient descent) or any of the methods supported by scipy.optimize.minimize.options (dict) – a dictionary with options for the different optimizers.
messages (bool) – If
Truethe loss evolution is shown during optimization.
Data Encoders#
We provide a family of algorithms that encode classical data into quantum circuits.
Binary encoder#
- qibo.models.encodings.binary_encoder(nqubits, parametrization='hyperspherical', data=None, codewords=None, keep_antictrls=False, backend=None, **kwargs)[source]#
Create circuit that encodes \(1\)-dimensional data in all amplitudes of the computational basis.
Given data vector \(\mathbf{x} \in \mathbb{C}^{d}\), with \(d = 2^{n}\), this function generates a quantum circuit \(\mathrm{Load}\) that encodes \(\mathbf{x}\) in the amplitudes of an \(n\)-qubit quantum state as
\[\mathrm{Load}(\mathbf{x}) \, \ket{0}^{\otimes \, n} = \sum_{j=0}^{d-1} \, \frac{x_{j}}{\|\mathbf{x}\|_{F}} \, \ket{b_{j}} \, ,\]where \(b_{j} \in \{0, \, 1\}^{\otimes \, n}\) is the \(n\)-bit representation of the integer \(j\), \(\|\cdot\|_{F}\) is the Frobenius norm.
Resulting circuit parametrizes
datainhyperspherical,hopf, ormottonencoordinates.- Parameters:
nqubits (int, optional) – total number of qubits in the system.
parametrization (str) – choice of state parametrization in the \((2^{n} - 1)\)-unit sphere. Either
hyperspherical,hopf, ormottonen. Ifdata is None, then circuit returned parametrizes real-valued quantum states. To return circuits that parametrize complex-valued states, options arehyperspherical-complex,hopf-complex, andmottonen-complex. Ifdata is not None, then data type is inferred fromdataand the suffix-complexdoes not need to be added. Defaults tohyperspherical.data (ArrayLike, optional) – \(1\)-dimensional array of length \(d = 2^{n}\) to be loaded in the amplitudes of a \(n\)-qubit quantum state. If
None, circuit is returned with all phases set to \(0.0\). Defaults toNone.codewords (int, optional) – list of codewords. When parametrization is
hyperspherical, the list is used to encode the data in the given order. IfNone, the codewords are set by the erhlich algorithm.keep_antictrls (bool, optional) – If
Trueand parametrization ishyperspherical, we don’t simplify the anti-controls when placing the RBS gates. For details, see [1].backend (
qibo.backends.abstract.Backend, optional) – backend to be used in the execution. IfNone, it uses the current backend. Defaults toNone.kwargs (dict, optional) – Additional arguments used to initialize a Circuit object. For details, see the documentation of
qibo.models.circuit.Circuit.
- Returns:
Circuit that loads
datain binary encoding.- Return type:
References
1. R. M. S. Farias, T. O. Maciel, G. Camilo, R. Lin, S. Ramos-Calderer, and L. Aolita, Quantum encoder for fixed-Hamming-weight subspaces Phys. Rev. Applied 23, 044014 (2025).
3. H. S. Cohl, Fourier, Gegenbauer and Jacobi expansions for a power-law fundamental solution of the polyharmonic equation and polyspherical addition theorems, Symmetry, Integrability and Geometry: Methods and Applications 10.3842/sigma.2013.042 (2013).
4. M. Möttönen, J. J. Vartiainen, V. Bergholm, and M. M. Salomaa, Transformation of quantum states using uniformly controlled rotations, arXiv:quant-ph/0407010 (2004).
Computational Basis Encoder#
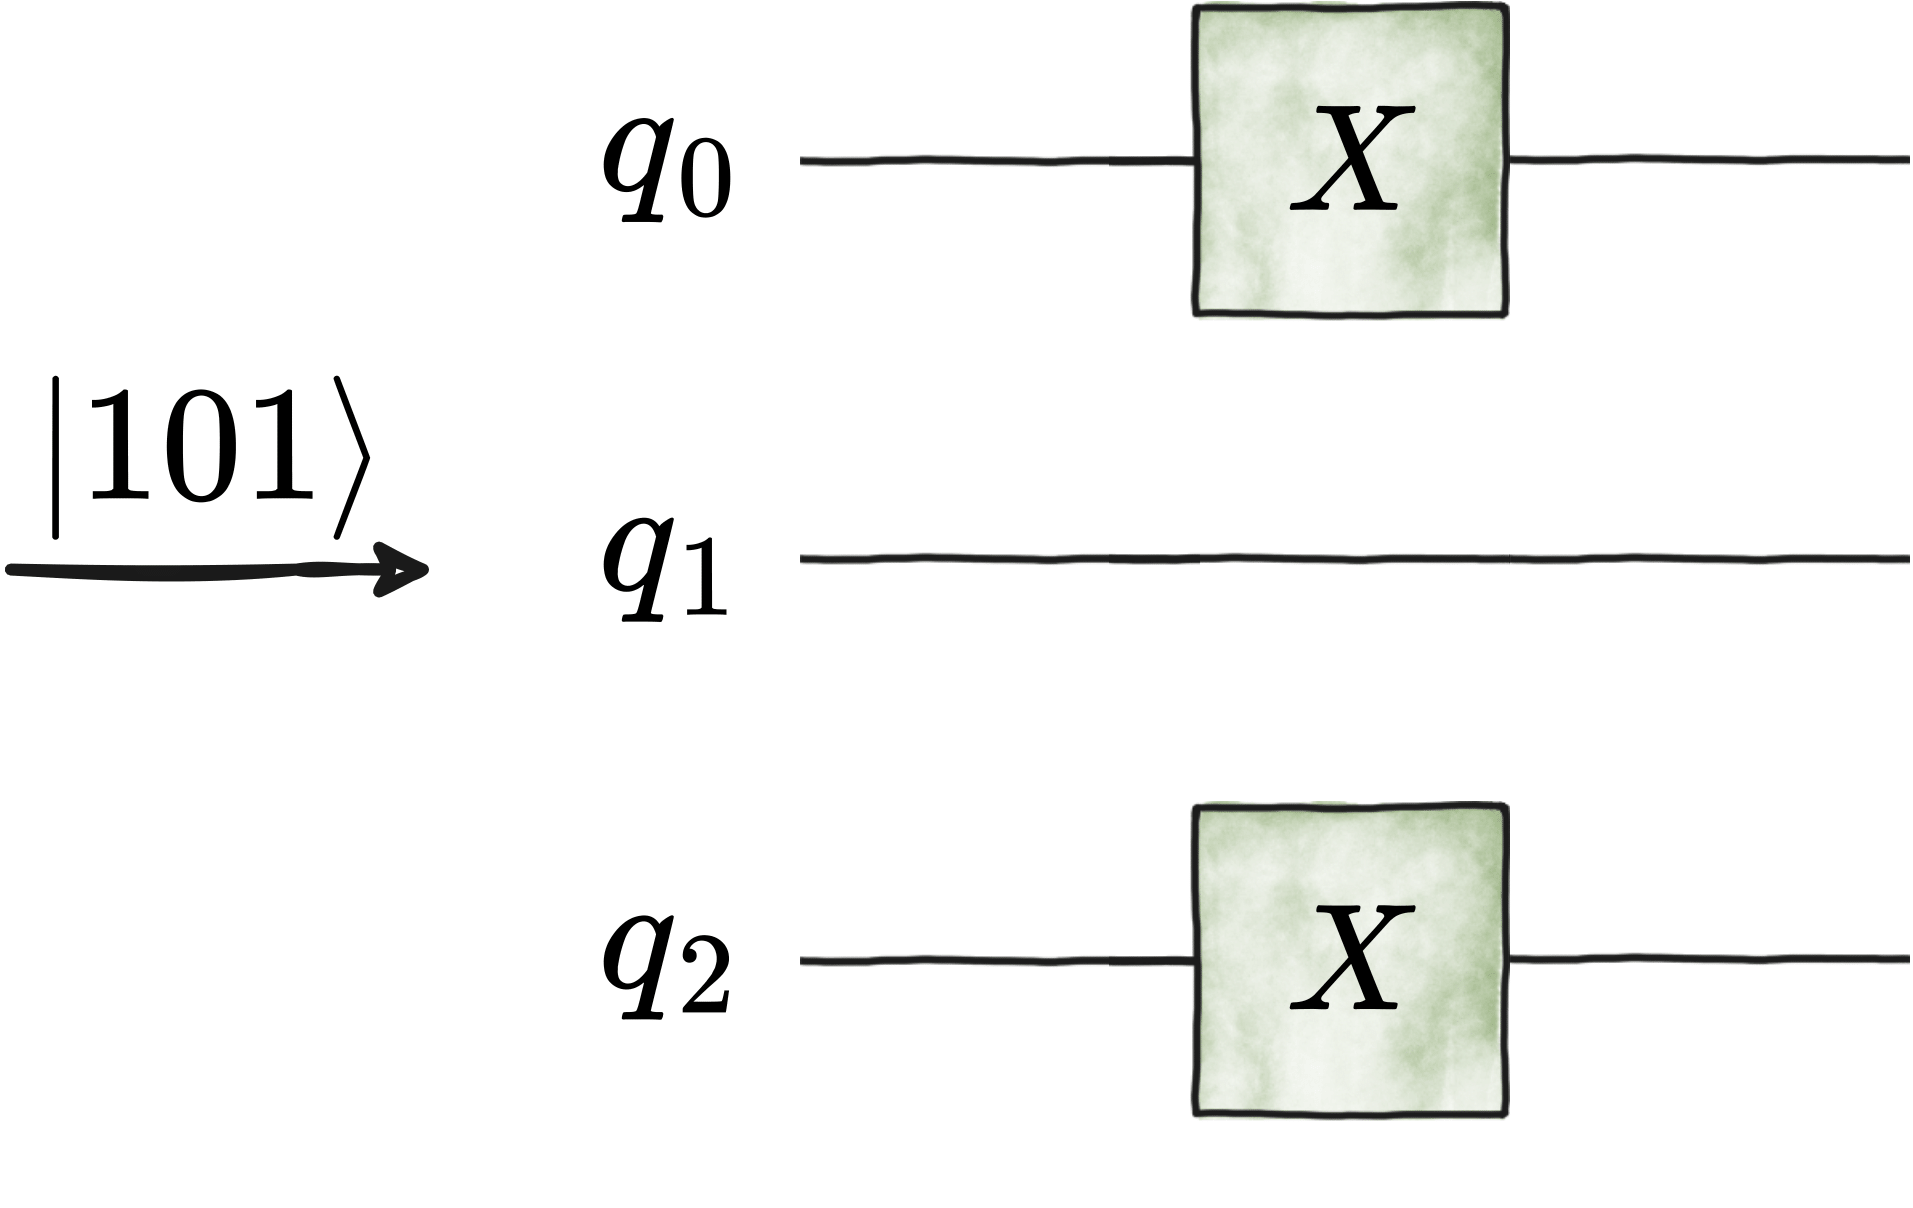
Given a bitstring \(b\) of length \(n\), this encoder generates a layer of Pauli-\(X\) gates that creates the quantum state \(|\,b\,\rangle\).
For instance, the following two circuit generations are equivalent:
b = "101"
circuit_1 = comp_basis_encoder(b)

circuit_2 = Circuit(3)
circuit_2.add(gates.X(0))
circuit_2.add(gates.X(2))
- qibo.models.encodings.comp_basis_encoder(basis_element, nqubits=None, **kwargs)[source]#
Create circuit that performs encoding of bitstrings into computational basis states.
- Parameters:
basis_element (int or str or list or tuple) – bitstring to be encoded. If
int,nqubitsmust be specified. Ifstr, must be composed of only \(0`s and :math:`1`s. If ``list`\) ortuple, must be composed of \(0`s and :math:`1`s as ``int`\) orstr.nqubits (int, optional) – total number of qubits in the circuit. If
basis_elementisint,nqubitsmust be specified. IfnqubitsisNone,nqubitsdefaults to length ofbasis_element. Defaults toNone.kwargs (dict, optional) – Additional arguments used to initialize a Circuit object. For details, see the documentation of
qibo.models.circuit.Circuit.
- Returns:
Circuit encoding computational basis element.
- Return type:
Dicke state#
- qibo.models.encodings.dicke_state(nqubits, weight, all_to_all=False, **kwargs)[source]#
Create a circuit that prepares the Dicke state \(\ket{D_{k}^{n}}\).
The Dicke state \(\ket{D_{k}^{n}}\) is the equal superposition of all \(n\)-qubit computational basis states with fixed-Hamming-weight \(k\). The circuit prepares the state deterministically with \(O(k \, n)\) gates and \(O(n)\) depth, or \(O(k \log\frac{n}{k})\) depth under the assumption of
all-to-allconnectivity.- Parameters:
nqubits (int) – number of qubits \(n\).
weight (int) – Hamming weight \(k\) of the Dicke state.
all_to_all (bool, optional) – If
False, uses implementation from Ref. [1]. IfTrue, uses shorter-depth implementation from Ref. [2]. Defaults toFalse.kwargs (dict, optional) – additional arguments used to initialize a Circuit object. For details, see the documentation of
qibo.models.circuit.Circuit.
- Returns:
Circuit that prepares \(\ket{D_{k}^{n}}\).
- Return type:
References
1. Andreas Bärtschi and Stephan Eidenbenz, Deterministic preparation of Dicke states, 22nd International Symposium on Fundamentals of Computation Theory, FCT’19, 126-139 (2019).
2. Andreas Bärtschi and Stephan Eidenbenz, Short-Depth Circuits for Dicke State Preparation, IEEE International Conference on Quantum Computing & Engineering (QCE), 87–96 (2022).
Entangling layer#
Generates a layer of nearest-neighbour two-qubit gates, assuming 1-dimensional connectivity.
With the exception of qibo.gates.gates.GeneralizedfSim,
any of the two-qubit gates implemented in qibo can be selected to customize the entangling layer.
If the chosen gate is parametrized, all phases are set to \(0.0\).
Note that these phases can be updated a posterior by using
qibo.models.Circuit.set_parameters().
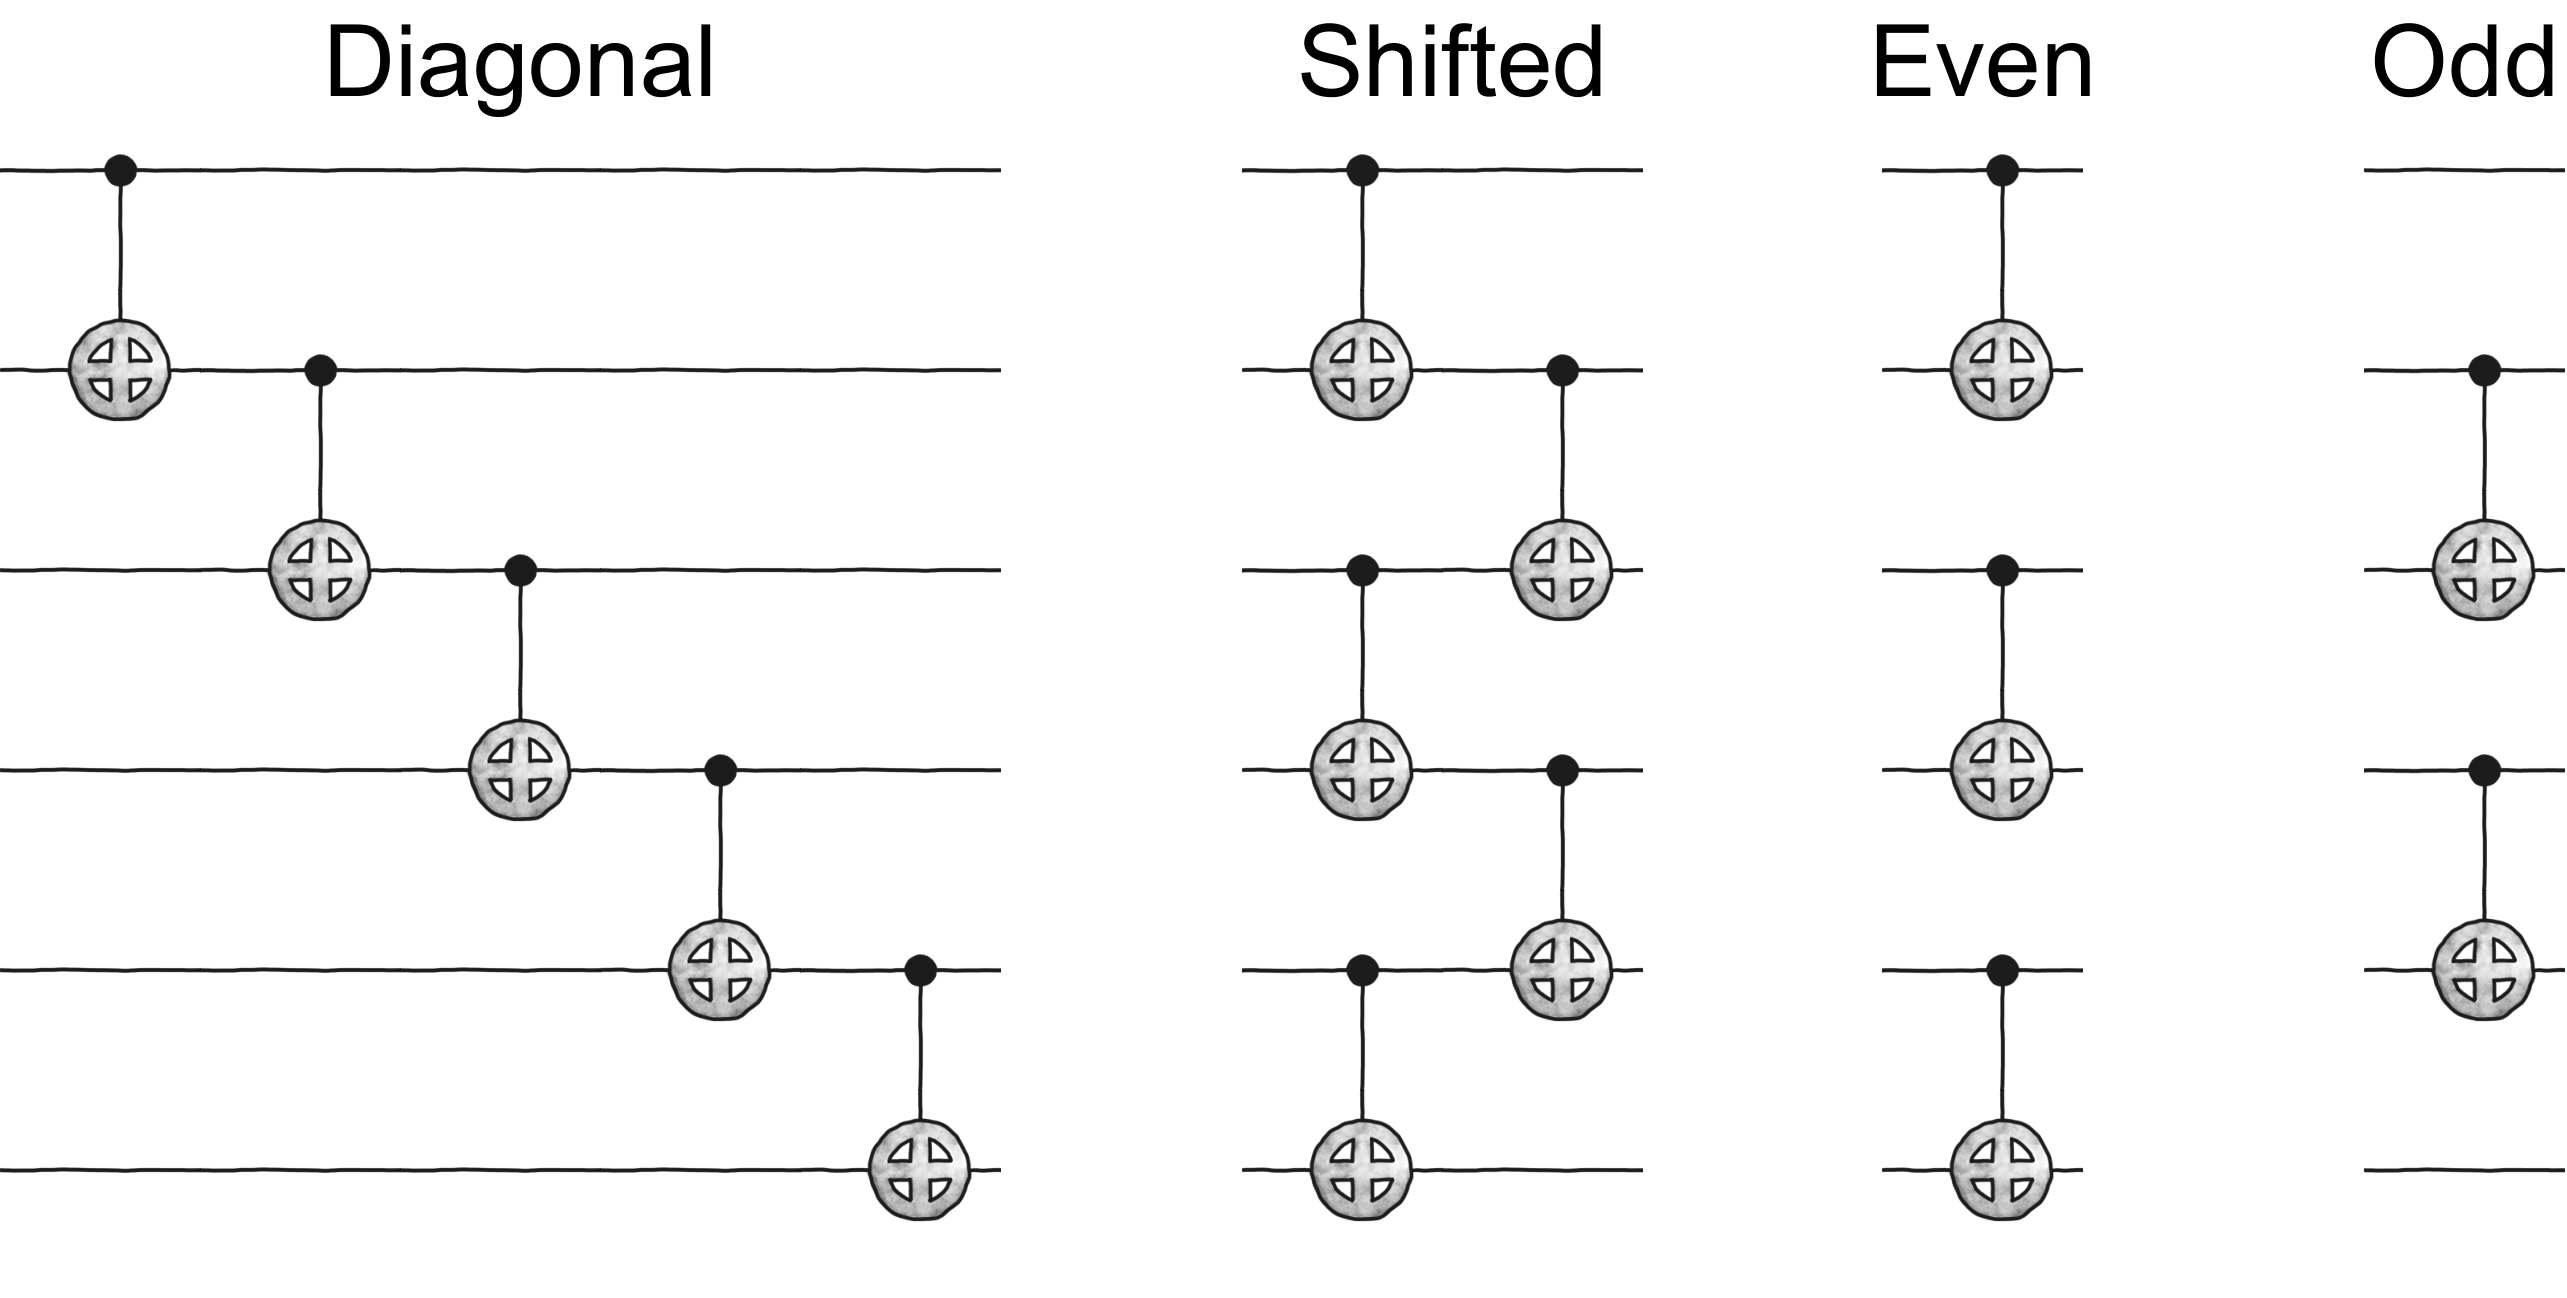
The possible choices of layer architecture are the following, in alphabetical order:
all-to-all, diagonal, even_layer, next_nearest, pyramid, odd_layer,
shifted, v, and x. For instance, we show below an example of four of those
architectures for nqubits = 6 and entangling_gate = "CNOT".
If closed_boundary is set to True, then an extra gate is added connecting the last and the first qubit,
with the last qubit as the control qubit and the first qubit as a target qubit.
- qibo.models.encodings.entangling_layer(nqubits, architecture='diagonal', entangling_gate='CNOT', closed_boundary=False, **kwargs)[source]#
Create a layer of two-qubit entangling gates.
If the chosen gate is a parametrized gate, all phases are set to \(0.0\).
- Parameters:
nqubits (int) – Total number of qubits in the circuit.
architecture (str, optional) – Architecture of the entangling layer. In alphabetical order, options are
"all-to-all","diagonal","even_layer","next_nearest","odd_layer","pyramid","shifted","v", and"x". The"all-to-all"architecture acts on all pairs of qubits \((j, k)\) with \(j < k\), ordered such that the depth of the layer is minimal: \(n - 1\) for even \(n\) and \(n\) for odd \(n\). The"x"architecture is only defined for an even number of qubits. Defaults to"diagonal".entangling_gate (str or
qibo.gates.Gate, optional) – Two-qubit gate to be used in the entangling layer. Ifentangling_gateis a parametrized gate, all phases are initialized as \(0.0\). Defaults to"CNOT".closed_boundary (bool, optional) – If
Trueandarchitecture not in ["all-to-all", "pyramid", "v", "x"], adds a closed-boundary condition to the entangling layer. Defaults toFalse.kwargs (dict, optional) – Additional arguments used to initialize a Circuit object. For details, see the documentation of
qibo.models.circuit.Circuit.
- Returns:
Circuit containing layer of two-qubit gates.
- Return type:
Greenberger-Horne-Zeilinger (GHZ) state#
- qibo.models.encodings.ghz_state(nqubits, **kwargs)[source]#
Generate an \(n\)-qubit Greenberger-Horne-Zeilinger (GHZ) state that takes the form
\[\ket{\text{GHZ}} = \frac{\ket{0}^{\otimes n} + \ket{1}^{\otimes n}}{\sqrt{2}}\]where \(n\) is the number of qubits.
- Parameters:
nqubits (int) – number of qubits \(n >= 2\).
kwargs (dict, optional) – additional arguments used to initialize a Circuit object. For details, see the documentation of
qibo.models.circuit.Circuit.
- Returns:
Circuit that prepares the GHZ state.
- Return type:
Graph state#
- qibo.models.encodings.graph_state(matrix, backend=None, **kwargs)[source]#
Create circuit encoding an undirected graph state given its adjacency matrix.
Given a graph \(G = (V, E)\) with \(V\) being the set of vertices and \(E\) being the set of edges, an $n$-qubit graph state is defined as
\[\ket{G} = \prod_{(j, k) \in E} \, CZ_{j, k} \, \ket{+}^{\otimes V} \, ,\]where \(CZ_{a,b}\) is the
qibo.gates.CZgate acting on qubits \(j\) and \(k\), and \(\ket{+} = H \, \ket{0}$, with :class:`qibo.gates.H\) being the Hadamard gate.- Parameters:
matrix (ArrayLike or list) – Adjacency matrix of the graph.
backend (
qibo.backends.abstract.Backend, optional) – backend to be used in the execution. IfNone, it uses the current backend. Defaults toNone.kwargs (dict, optional) – Additional arguments used to initialize a Circuit object. For details, see the documentation of
qibo.models.circuit.Circuit.
- Returns:
Circuit of the graph state with the given adjacency matrix.
- Return type:
Grover-Rudolph state preparation#
- qibo.models.encodings.grover_rudolph(distribution, parametrization='hopf', backend=None, **kwargs)[source]#
Create circuit that loads a discrete probability distribution in the amplitudes.
Given a non-negative vector \(\mathbf{p} \in \mathbb{R}_{\geq 0}^{d}\), with \(d = 2^{n}\), this function generates a circuit that prepares
\[\sum_{j=0}^{d-1} \, \sqrt{\frac{p_{j}}{\|\mathbf{p}\|_{1}}} \, \ket{b_{j}} \, ,\]where \(b_{j} \in \{0, \, 1\}^{\otimes \, n}\) is the \(n\)-bit representation of the integer \(j\). It is a wrapper of
qibo.models.encodings.binary_encoder().- Parameters:
distribution (ArrayLike) – \(1\)-dimensional array with non-negative entries and length \(2^{n}\). It does not need to be normalized.
parametrization (str, optional) – either
hopformottonen. Defaults tohopf.backend (
qibo.backends.abstract.Backend, optional) – backend to be used in the execution. IfNone, it uses the current backend. Defaults toNone.kwargs (dict, optional) – Additional arguments used to initialize a Circuit object. For details, see the documentation of
qibo.models.circuit.Circuit.
- Returns:
Circuit that loads
distribution.- Return type:
References
1. L. Grover and T. Rudolph, Creating superpositions that correspond to efficiently integrable probability distributions, arXiv:quant-ph/0208112.
Fanout gate synthesis in log depth#
- qibo.models.encodings.fanout_synthesis(qubits, nqubits=None, method=None, **kwargs)[source]#
Synthesis of the Fanout gate in logarithmic depth.
Implementation based on applying Ref. [1, Algorithm 1] twice.
- Parameters:
qubits (list[int] | tuple[int]) – qubits in which the CNOT ladder acts on.
nqubits (int, optional) – total number of qubits in the circuit. To be used when the total number of qubits differ from len(qubits). Defaults to
None.method (str, optional) – if “parity”, return a fanout decomposition based on parity trees. If
None, return a decomposition based on CNOT-ladder synthesis. Defaults toNone.
- Returns:
Circuit containing the sequence of gates in parallel.
- Return type:
References
1. M. Remaud and V. Vanndaele, Ancilla-free quantum adder with sublinear depth, In: Glück, R., Kaarsgaard, R. (eds) Reversible Computation. RC 2025. Lecture Notes in Computer Science, vol 15716. Springer, Cham. (2025).
Folded XXZ eigenstates#
Prepares the eigenstates of the spin-\(1/2\) folded XXZ chain with open boundary conditions, a kinetically constrained integrable model whose Hilbert space is fragmented into exponentially many dynamically disconnected sectors. Its eigenstates contain magnons, which are delocalized, and static domain walls, which are displaced when a magnon crosses them. The number of gates grows polynomially with the number of sites and with the number of magnons. For instance, the following eigenstate of five sites has a single magnon and two domain walls, and it is a superposition of two spin configurations.
from qibo.models.encodings import folded_xxz_eigenstate

circuit = folded_xxz_eigenstate(nsites=5, nmagnons=1, domains=[[3, 4]], modes=[2])
result = circuit()
# the chain is encoded in the first five qubits, and the remaining ones are auxiliary
probabilities = result.probabilities(qubits=range(5))
print(*(f"{state}: {prob:.2f}" for state, prob in zip(
    ("10110", "11001"), probabilities[[0b10110, 0b11001]]
)))
The circuit can be implemented with two methods, selected with method. The default
"sopena" follows the original construction. With "merged", the free fermions are prepared
with Givens rotations, and the output is written in a single pass over the squeezed chain.
For domain walls, "merged" needs fewer qubits and gates, and for no domain walls, it needs more.
Both prepare the same state in the first qubits of the circuit.
circuit = folded_xxz_eigenstate(5, 1, [[3, 4]], [2], method="merged")
probabilities = circuit().probabilities(qubits=range(5))
print(*(f"{state}: {prob:.2f}" for state, prob in zip(
    ("10110", "11001"), probabilities[[0b10110, 0b11001]]
)))
- qibo.models.encodings.folded_xxz_eigenstate(nsites, nmagnons, domains=None, modes=None, method='sopena', return_toffolis=False, backend=None)[source]#
Create circuit that prepares an eigenstate of the open-boundary folded XXZ spin chain.
Let \(n\) be the number of sites of the chain. The folded XXZ Hamiltonian is
\[H = -\frac{1}{8} \sum_{j=0}^{n-2} \left(1 + Z_{j} Z_{j+3}\right) \left(X_{j+1} X_{j+2} + Y_{j+1} Y_{j+2}\right) \, ,\]where the boundary sites \(0\) and \(n + 1\) are frozen to \(\ket{0}\). These two sites are not part of the register, which holds sites \(1, \ldots, n\), with site \(1\) being the first qubit. Spin-down sites are the \(\ket{1}\) states. Its dynamics is kinetically constrained, and the Hilbert space splits into independent fragments. An eigenstate \(\ket{\psi}\) of a fragment contains
\(M\) magnons, which are isolated spin-down sites in a spin-up domain (particles) or isolated spin-up sites in a spin-down domain (holes), and
\(2 L\) static domain walls, which delimit \(L\) blocks of spin-down sites, and are displaced by two sites each time a magnon crosses them.
The fragment is fixed by the number of magnons and by the blocks
domainsof the reference configuration, in which the magnons are packed to the left at the lowest allowed positions, i.e. at sites \(1, 3, \ldots, 2M - 1\). The magnons have momenta \(p_{a} = \pi \, m_{a} / (n_{0} + 1)\), with \(n_{0} = n - M + 1 - 2L\) and \(m_{1} < \cdots < m_{M}\) integers in \([1, n_{0}]\), and the energy is \(E = -\sum_{a=1}^{M} \cos(p_{a})\). The circuit has three stages following Ref. [1]: the preparation of a Slater determinant of \(M\) free fermions in a squeezed chain of \(n_{0}\) sites, which needs \(n_{0} \geq 2M\); a network of controlled-SWAP gates that enforces the hard-core repulsion between magnons; and the insertion of the domain walls. These stages can be implemented with two different methods. With"sopena", the free fermions are prepared with the algebraic Bethe circuit of Refs. [2, 3], which starts from a dense unitary on \(2M\) qubits and limits \(M\) to a few. Then, the magnons are shifted in place, and inserted one by one in the chain with the domain walls. With"merged", the free fermions are prepared with \(M (n_{0} - 1) - M (M - 1) / 2\) Givens rotations (see Refs. [4, 5]), and the last two stages are performed at once: a single pass over the squeezed chain writes the output in a separate register, and a second pass clears the input from the output. For domain walls, it needs fewer qubits and gates, and for no domain walls, it needs more.The first
nsitesqubits of the circuit hold the chain. The remaining qubits are auxiliary qubits, which are returned to \(\ket{0}\), and thus the state of the chain can be read out by discarding them.- Parameters:
nsites (int) – number of sites \(n\) of the chain.
nmagnons (int) – number of magnons \(M\).
domains (list[list[int]], optional) – blocks of spin-down sites of the reference configuration. Each block is a list of at least two consecutive sites, numbered from \(1\). The first block must start at site \(2M + 1\) or later, and each following block must start at least three sites after the end of the previous one. If
None, there are no domain walls. Defaults toNone.modes (list[int], optional) – integers \(m_{1} < \cdots < m_{M}\) that fix the momenta of the magnons. If
None, uses \(M\) evenly spaced integers between \(2\) and \(n_{0}\), rounded to the nearest integer. Defaults toNone.method (str, optional) – implementation of the circuit, either
"sopena", following Ref. [1], or"merged". Defaults to"sopena".return_toffolis (bool, optional) – only used if
method="merged". IfTrue, the Toffoli gates are returned asqibo.gates.TOFFOLIgates, which are not decomposed into CNOTs and single-qubit rotations. Otherwise, they are implemented up to a relative phase with CNOTs and single-qubit rotations. Defaults toFalse.backend (
qibo.backends.abstract.Backend, optional) – backend to be used in the execution. IfNone, it uses the current backend. Defaults toNone.
- Returns:
circuit that prepares the eigenstate.
- Return type:
References
1. R. Ruiz, A. Sopena, B. Pozsgay, and E. López, Efficient Eigenstate Preparation in an Integrable Model with Hilbert Space Fragmentation, PRX Quantum 6, 030316 (2025).
2. A. Sopena, M. H. Gordon, D. García-Martín, G. Sierra, and E. López, Algebraic Bethe Circuits, Quantum 6, 796 (2022).
3. R. Ruiz, A. Sopena, M. H. Gordon, G. Sierra, and E. López, The Bethe Ansatz as a Quantum Circuit, Quantum 8, 1356 (2024).
4. Z. Jiang, K. J. Sung, K. Kechedzhi, V. N. Smelyanskiy, and S. Boixo, Quantum algorithms to simulate many-body physics of correlated fermions, Phys. Rev. Applied 9, 044036 (2018).
5. I. D. Kivlichan, J. McClean, N. Wiebe, C. Gidney, A. Aspuru-Guzik, G. K.-L. Chan, and R. Babbush, Quantum simulation of electronic structure with linear depth and connectivity, Phys. Rev. Lett. 120, 110501 (2018).
Fixed Hamming-weight Encoder#
- qibo.models.encodings.hamming_weight_encoder(nqubits, weight, data=None, complex_data=False, full_hwp=False, optimize_controls=True, phase_correction=True, initial_string=None, backend=None, **kwargs)[source]#
Create circuit that encodes
datain the Hamming-weight-\(k\) basis ofnqubits.Let \(\mathbf{x}\) be a \(1\)-dimensional array of size \(d = \binom{n}{k}\) and \(B_{k} \equiv \{ \ket{b_{j}} : b_{j} \in \{0, 1\}^{\otimes n} \,\, \text{and} \,\, |b_{j}| = k \}\) be a set of \(d\) computational basis states of \(n\) qubits that are represented by bitstrings of Hamming weight \(k\). Then, an amplitude encoder in the basis \(B_{k}\) is an \(n\)-qubit parameterized quantum circuit \(\operatorname{Load}_{B_{k}}\) such that
\[\operatorname{Load}(\mathbf{x}) \, \ket{0}^{\otimes n} = \frac{1}{\|\mathbf{x}\|} \, \sum_{j = 1}^{d} \, x_{j} \, \ket{b_{j}}\]- Parameters:
nqubits (int) – number of qubits.
weight (int) – Hamming weight that defines the subspace in which
datawill be encoded.data (ArrayLike, optional) – \(1\)-dimensional array of data to be loaded. If
None, circuit is returned with all phases set to \(0.0\). Defaults toNone.complex_data (bool, optional) – to be used when
data is None. IfTrue, returned circuit parametrizes complex-valued states. IfFalse, it parametrizes real-valued states. Ifdata is not None, then data type is inferred fromdata. Defaults toFalse.full_hwp (bool, optional) – if
False, includes Pauli-\(X\) gates that prepare the first bitstring of Hamming weightk = weight. IfTrue, circuit is full Hamming weight preserving. Defaults to`False.optimize_controls (bool, optional) – if
True, removes unnecessary controlled operations. Defaults toTrue.phase_correction (bool, optional) – To be used when
datais complex-valued. IfTrue, adds a controlled-$mathrm{RZ}$ gate to the end of the circuit, adding a final phase correction. IfFalse, gate is not added. Defaults toTrue.initial_string (ArrayLike, optional) – Array containing the desired initial bitstring of Hamming
weight$k$. IfNone, defaults to $ket{1^{k}0^{n-k}}$. Defaults toNone.backend (
qibo.backends.abstract.Backend, optional) – backend to be used in the execution. IfNone, it uses the current backend. Defaults toNone.kwargs (dict, optional) – Additional arguments used to initialize a Circuit object. For details, see the documentation of
qibo.models.circuit.Circuit.
- Returns:
Circuit that loads
datain Hamming-weight-\(k\) representation.- Return type:
References
1. R. M. S. Farias, T. O. Maciel, G. Camilo, R. Lin, S. Ramos-Calderer, and L. Aolita, Quantum encoder for fixed-Hamming-weight subspaces Phys. Rev. Applied 23, 044014 (2025).
CNOT ladder synthesis in log depth#
- qibo.models.encodings.ladder_synthesis(qubits, nqubits=None, return_circuit=False, **kwargs)[source]#
Synthesis of the CNOT ladder operator in logarithmic depth.
Implementation based on Ref. [1, Algorithm 1].
- Parameters:
qubits (list[int] | tuple[int]) – qubits in which the CNOT ladder acts on.
nqubits (int, optional) – total number of qubits in the circuit. To be used when return_circuit=True and the total number of qubits differ from len(qubits). Defaults to
None.return_circuit (bool, optional) – if
True, returns aqibo.models.circuit.Circuitclass. IfFalse, returns a list with the sequence ofqibo.gates.CNOTgates in parallel. Defaults toFalse.
- Returns:
List of gates or circuit containing the sequence of gates.
- Return type:
list or
qibo.models.circuit.Circuit
References
1. M. Remaud and V. Vanndaele, Ancilla-free quantum adder with sublinear depth, In: Glück, R., Kaarsgaard, R. (eds) Reversible Computation. RC 2025. Lecture Notes in Computer Science, vol 15716. Springer, Cham. (2025).
Leaf-separable Encoder#
Prepares states of fixed Hamming weight whose qubits are split in contiguous groups (leaves),
such that, for each distribution of the weight among the leaves, the state is a product over
leaves. The leaves are correlated only through the weight distribution.
The circuit follows the algorithm of Vittal et al. (arXiv:2511.11227): a balanced binary tree of
generalized weight distribution blocks, as in qibo.models.encodings.dicke_state(), followed
by Hamming weight encoders acting on the leaves. It supports real and complex amplitudes
and needs no auxiliary qubits.
For instance, the Dicke state \(\ket{D_{2}^{6}}\) is leaf-separable, and the following example prepares it on \(6\) qubits split in leaves of \(2\) qubits.
nqubits, weight, leaf_size = 6, 2, 2

# amplitudes of the 15 basis states of Hamming weight 2, in ascending order
data = np.ones(15)

circuit = leaf_separable_encoder(nqubits, weight, leaf_size, data)
- qibo.models.encodings.leaf_separable_encoder(nqubits, weight, leaf_size, data, backend=None, **kwargs)[source]#
Create a circuit that encodes a leaf-separable
datain the Hamming-weight-\(k\) basis ofnqubits.The \(n\) qubits are split in \(G = \lceil n / s \rceil\) contiguous sets of \(s\) qubits, called leaves (the last leaf holds the remaining \(n \bmod s\) qubits), with \(k \leq s\). Given a leaf \(u\), let \(i_{u}\) be the Hamming weight of a bitstring restricted to it, and \(I = (i_{1}, \dots, i_{G})\) the weight distribution of the bitstring. An \(n\)-qubit state with Hamming weight \(k\) is leaf-separable if, for every \(I\), its component with weight distribution \(I\) is a product state over the leaves, i.e.,
\[\ket{\psi} = \sum_{I} \, c(I) \, \bigotimes_{u=1}^{G} \ket{\psi_{i_{u}}} \, ,\]where \(c(I) \in \mathbb{C}\) and \(\ket{\psi_{i_{u}}}\) is a state of leaf \(u\) with Hamming weight \(i_{u}\). The state itself is not a product state, since the leaves are correlated through \(c(I)\).
The circuit follows Ref. [1] and uses no auxiliary qubits. First, the leaves are placed at the leaves of a balanced binary tree, built by recursively splitting the ordered list of leaves in two halves, and the total weight \(k\) is distributed among them with a generalized weight distribution block (gWDB) at each internal node, from the root down. A gWDB is the weight distribution block of
qibo.models.encodings.dicke_state()[3], with the uniform distribution of weights replaced by the one ofdata, followed by controlled phase gates that account for the phase of \(c(I)\). Then, on each leaf, it applies a Hamming weight encoder for each weight \(i_{u}\) (seeqibo.models.encodings.hamming_weight_encoder()), with all its gates controlled on the whole leaf, so that it acts only on the sector of leaf weight \(i_{u}\). The circuit has depth \(O(s \, \log\frac{n}{s} + s \, 2^{s})\).Note
A gWDB only knows the weight of its own node. Hence, the tree prepares \(|c(I)|\) as a product of conditional weight distributions, one for each node, computed from the marginals of
data, and the phase of \(c(I)\) as a sum of phases that depend only on the weights of each node. The output state is equal todataif \(c(I)\) has that form, which is always the case if there are only two leaves, i.e., \(s \geq n / 2\), as stated in Ref. [1], and also if there are three leaves, since \(I\) is then fixed by the weights of the two nodes. Phases that are sums of functions of the weight of each leaf, e.g., global phases of the leaf states, are always reproduced. Otherwise, correlations between the weights of different leaves that are not captured by the tree are lost, and the output state is an approximation ofdata. In that case, the phase of each node is chosen by alternating maximization of the overlap withdata, as Ref. [1] does not specify it, and a warning is logged if it does not converge.- Parameters:
nqubits (int) – number of qubits \(n\).
weight (int) – Hamming weight \(k\) of the state.
leaf_size (int) – number of qubits \(s\) in each leaf. It must satisfy \(k \leq s < n\).
data (ArrayLike) – \(1\)-dimensional array of \(\binom{n}{k}\) real or complex amplitudes, ordered by the integer value of the corresponding computational basis states, i.e., as in
qibo.models.encodings.hamming_weight_encoder(). It is normalized internally. The state defined bydatamust be leaf-separable.backend (
qibo.backends.abstract.Backend, optional) – backend to be used in the execution. IfNone, it uses the current backend. Defaults toNone.kwargs (dict, optional) – Additional arguments used to initialize a Circuit object. For details, see the documentation of
qibo.models.circuit.Circuit.
- Returns:
Circuit that prepares the leaf-separable state defined by
data.- Return type:
References
1. S. Vittal, A. Wilkie, N. Rastegari, M. Atallah, and R. Herrman, Efficient circuits for leaf-separable state preparation, arXiv:2511.11227 [quant-ph] (2025).
2. R. M. S. Farias, T. O. Maciel, G. Camilo, R. Lin, S. Ramos-Calderer, and L. Aolita, Quantum encoder for fixed-Hamming-weight subspaces Phys. Rev. Applied 23, 044014 (2025).
3. Andreas Bärtschi and Stephan Eidenbenz, Short-Depth Circuits for Dicke State Preparation, IEEE International Conference on Quantum Computing & Engineering (QCE), 87–96 (2022).
Permutation synthesis#
- qibo.models.encodings.permutation_synthesis(sigma, m=2, backend=None, **kwargs)[source]#
Return circuit that implements a given permutation.
Given permutation
sigmaon \(\{0, \, 1, \, \dots, \, d-1\}\) and a power‑of‑two budgetm, this function factorssigmainto the fewest layers \(\sigma_{1}, \, \sigma_{2}, \, \cdots, \, \sigma_{t}\) such that: - each layer has at most \(m\) disjoint transpositions; - each layer moves a power‑of‑two number of indices.The function returns a circuit synthesis of
sigma.- Parameters:
sigma (list or tuple) – permutation description on \(\{0, \, 1, \, \dots, \, d-1\}\).
m (int) – power‑of‑two budget. Defauls to \(2\).
backend (
qibo.backends.abstract.Backend, optional) – backend to be used in the execution. IfNone, it uses the current backend. Defaults toNone.kwargs (dict, optional) – Additional arguments used to initialize a Circuit object. For details, see the documentation of
qibo.models.circuit.Circuit.
- Returns:
Circuit that implements the permutation
sigma.- Return type:
References
1. L. Li, and J. Luo, Nearly Optimal Circuit Size for Sparse Quantum State Preparation arXiv:2406.16142 (2024).
Phase Encoder#
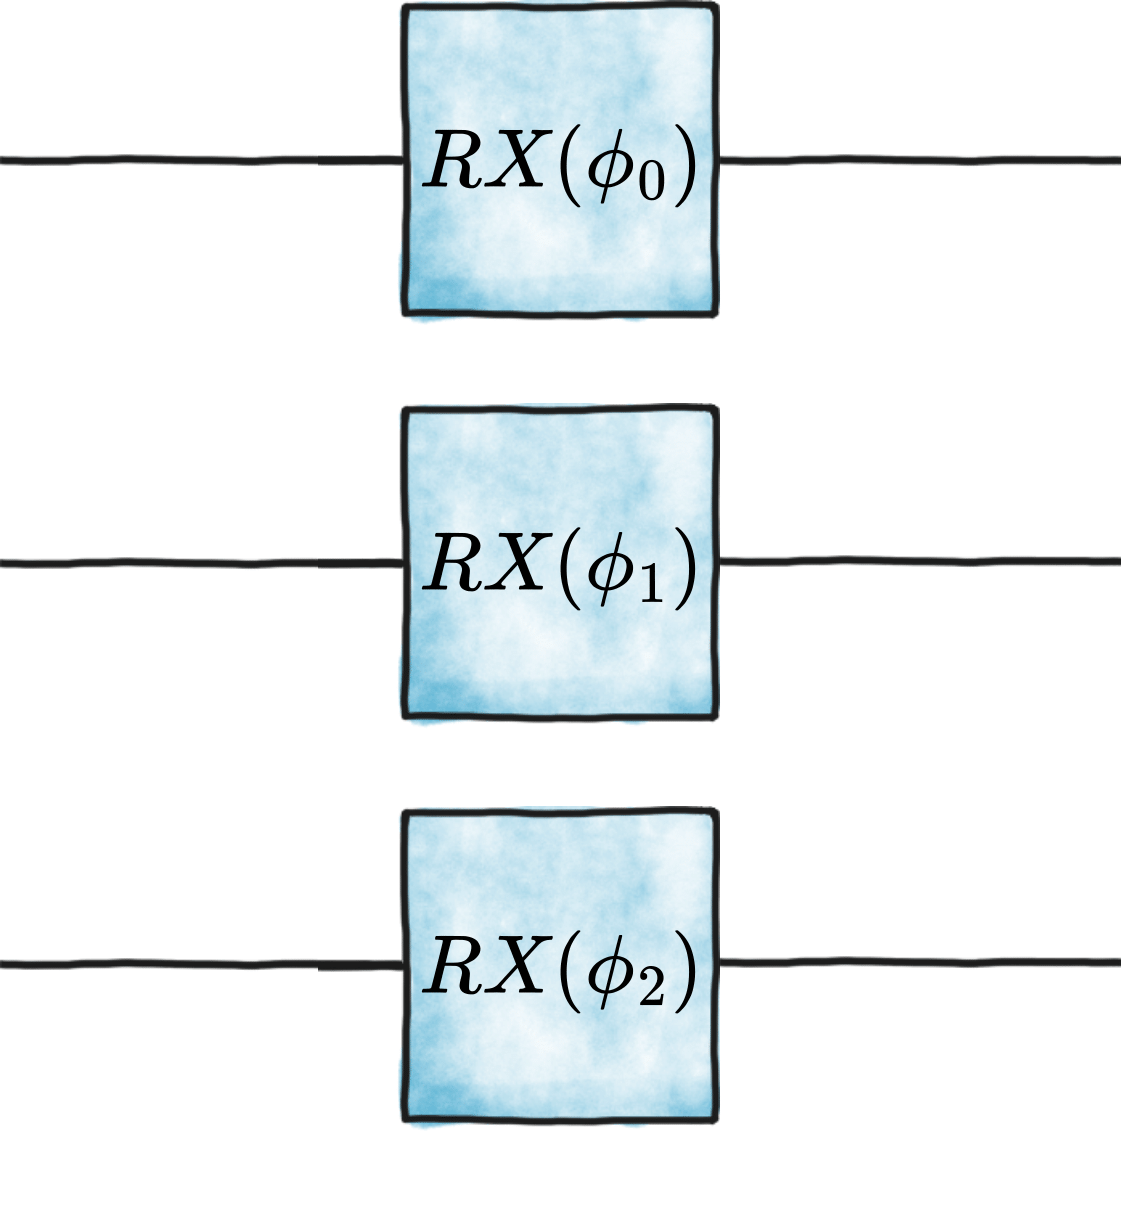
Encodes data of length \(n\) into the phases of \(n\) qubits.
For instance, the following two circuit generations are equivalent:
nqubits = 3
phases = np.random.rand(nqubits)

circuit_1 = phase_encoder(nqubits, rotation="RX", data=phases)

circuit_2 = Circuit(3)
circuit_2.add(gates.RX(qubit, phases[qubit]) for qubit in range(nqubits))
- qibo.models.encodings.phase_encoder(nqubits, rotation='RY', data=None, backend=None, **kwargs)[source]#
Create circuit that performs the phase encoding of
data.- Parameters:
nqubits (int) – number of qubits in the system.
rotation (str, optional) – If
"RX", usesqibo.gates.gates.RXas rotation. If"RY", usesqibo.gates.gates.RYas rotation. If"RZ", usesqibo.gates.gates.RZas rotation. Defaults to"RY".data (ArrayLike) – \(1\)-dimensional array of phases to be loaded. If
None, all phases of the circuit are set to \(0.0\). Defaults toNone.backend (
qibo.backends.abstract.Backend, optional) – backend to be used in the execution. IfNone, it uses the current backend. Defaults toNone.kwargs (dict, optional) – Additional arguments used to initialize a Circuit object. For details, see the documentation of
qibo.models.circuit.Circuit.
- Returns:
Circuit that loads
datain phase encoding.- Return type:
Sparse encoder#
- qibo.models.encodings.sparse_encoder(data, method='li', nqubits=None, backend=None, **kwargs)[source]#
Create circuit that encodes \(1\)-dimensional data in a subset of amplitudes of the computational basis.
Consider a sparse-access model, where for a data vector \(\mathbf{x} \in \mathbb{C}^{d}\), with \(d = 2^{n}\) and \(s\) non-zero amplitudes, one has access to the data vector \(\mathbf{y}\) of the form
\[\mathbf{y} = \left\{ (b_{1}, x_{1}), \, \dots, \, (b_{s}, x_{s}) \right\} \, ,\]where \(\{x_{j}\}_{j\in[s]}\) is the non-zero components of \(\mathbf{x}\) and \(\{b_{j}\}_{j\in[s]}\) is the set of addresses associated with these values. Then, this function generates a quantum circuit \(s\text{-}\mathrm{Load}\) that encodes \(\mathbf{x}\) in the amplitudes of an \(n\)-qubit quantum state as
\[s\text{-}\mathrm{Load}(\mathbf{y}) \, \ket{0}^{\otimes \, n} = \sum_{j\in[s]} \, \frac{x_{j}}{\|\mathbf{x}\|_{2}} \, \ket{b_{j}} \, ,\]where \(\|\cdot\|_{2}\) is the Euclidean norm.
The resulting circuit parametrizes
datain hyperspherical coordinates in the \((2^{n} - 1)\)-unit sphere.- Parameters:
data (ArrayLike or list or zip) – sequence of tuples of the form \((b_{j}, x_{j})\). The addresses \(b_{j}\) can be either integers or in bitstring format of size \(n\).
method (str, optional) – method to be used, either
liorfarias. They refer to methods in references [1] and [2], respectively. Defaults tolinqubits (int, optional) – total number of qubits in the system. To be used when \(b_j\) are integers. If \(b_j\) are strings and
nqubitsisNone, defaults to the length of the strings \(b_{j}\). Defaults toNone.backend (
qibo.backends.abstract.Backend, optional) – backend to be used in the execution. IfNone, it uses the current backend. Defaults toNone.kwargs (dict, optional) – Additional arguments used to initialize a Circuit object. For details, see the documentation of
qibo.models.circuit.Circuit.
- Returns:
Circuit that loads sparse \(\mathbf{x}\).
- Return type:
References
1. L. Li, and J. Luo, Nearly optimal circuit size for sparse quantum state preparation arXiv:2406.16142 (2024).
2. R. M. S. Farias, T. O. Maciel, G. Camilo, R. Lin, S. Ramos-Calderer, and L. Aolita, Quantum encoder for fixed-Hamming-weight subspaces, Phys. Rev. Applied 23, 044014 (2025).
Spin-\(s\) fixed-magnetization Encoder#
Generalization of the fixed Hamming-weight encoder to chains of \(n\) spin-\(s\) sites, loading data into the eigenspace of total magnetization \(S^{z}\). Each site is mapped into qubits via either a unary or a binary encoding.
- qibo.models.encodings.spin_s_encoder(nqudits, spin, weight, data=None, complex_data=False, encoding='unary', optimize_controls=True, phase_correction=True, backend=None, **kwargs)[source]#
Create circuit encoding
datain a fixed-\(S^{z}\) subspace of a spin-\(s\) chain.Let \(\mathbf{x}\) be a \(1\)-dimensional array of size \(D\) and \(B_{k} \equiv \{ \ket{\mathbf{m}} : \mathbf{m} \in \{0, 1, \ldots, 2s\}^{n} \,\, \text{and} \,\, \sum_{r} m_{r} = k \}\) be the set of \(D\) computational basis states of \(n\) spin-\(s\) sites (equivalently, \((2s + 1)\)-level qudits) whose ditstrings \(\mathbf{m}\) have fixed digit sum \(k\). Then, this function returns a circuit \(\operatorname{Load}_{B_{k}}\) such that
\[\operatorname{Load}(\mathbf{x}) \, \ket{0}^{\otimes n} = \frac{1}{\|\mathbf{x}\|} \, \sum_{j = 1}^{D} \, x_{j} \, \ket{\mathbf{m}_{j}} \, ,\]where the ditstrings \(\mathbf{m}_{j}\) are sorted in lexicographical order, with site \(0\) being the most significant digit. The construction follows Refs. [1, 2]. For \(s = 1/2\), this reduces to the fixed-Hamming-weight encoder of Ref. [3], implemented in
qibo.models.encodings.hamming_weight_encoder().- Parameters:
nqudits (int) – number of spin-\(s\) sites \(n\).
spin (float) – spin \(s \in \{1/2, \, 1, \, 3/2, \, \ldots\}\) of each site.
weight (int) – digit sum \(k \in \{0, \, 1, \, \ldots, \, 2sn\}\) that defines the subspace in which
datawill be encoded.data (ArrayLike, optional) – \(1\)-dimensional array of data to be loaded. If
None, circuit is returned with all phases set to \(0.0\). Defaults toNone.complex_data (bool, optional) – to be used when
data is None. IfTrue, returned circuit parametrizes complex-valued states. IfFalse, it parametrizes real-valued states. Ifdata is not None, then data type is inferred fromdata. Defaults toFalse.encoding (str, optional) – mapping of each \((2s + 1)\)-level site into qubits. Options are
"unary"and"binary". Defaults to"unary".optimize_controls (bool, optional) – if
True, removes redundant controls on sites that were not modified by previous Gray gates, following Sec. 2.2.1 of Ref. [1]. Defaults toTrue.phase_correction (bool, optional) – To be used when
datais complex-valued. IfTrue, adds a controlled-\(\mathrm{RZ}\) gate to the end of the circuit, adding a final phase correction. IfFalse, gate is not added. Defaults toTrue.backend (
qibo.backends.abstract.Backend, optional) – backend to be used in the execution. IfNone, it uses the current backend. Defaults toNone.kwargs (dict, optional) – Additional arguments used to initialize a Circuit object. For details, see the documentation of
qibo.models.circuit.Circuit.
- Returns:
Circuit that loads
datain the fixed-digit-sum subspace of \(n\) spin-\(s\) sites.- Return type:
References
1. N. Zare Harofteh and R. I. Nepomechie, Spin-s U(1)-eigenstate preparation, Ann. Phys. (Berlin) 538, e70239 (2026).
2. T. R. Walsh, Loop-free sequencing of bounded integer compositions, J. Comb. Math. Comb. Comp. 33, 323 (2000).
3. R. M. S. Farias, T. O. Maciel, G. Camilo, R. Lin, S. Ramos-Calderer, and L. Aolita, Quantum encoder for fixed-Hamming-weight subspaces Phys. Rev. Applied 23, 044014 (2025).
Unary Encoder#
Given a classical data array \(\mathbf{x} \in \mathbb{R}^{d}\) such that
this function generate the circuit that prepares the following quantum state \(\ket{\psi} \in \mathcal{H}\):
with \(\mathcal{H} \cong \mathbb{C}^{d}\) being a \(d\)-qubit Hilbert space, and \(\|\cdot\|_{\textup{HS}}\) being the Hilbert-Schmidt norm.
Here, \(\ket{k}\) is a unary representation of the number \(k\). For instance, for \(d = 3\), the final state would be
There are multiple circuit architechtures that lead to unary encoding of classical data. For example, to encode a \(8\)-dimensional data, one could use the so-called tree architechture below:
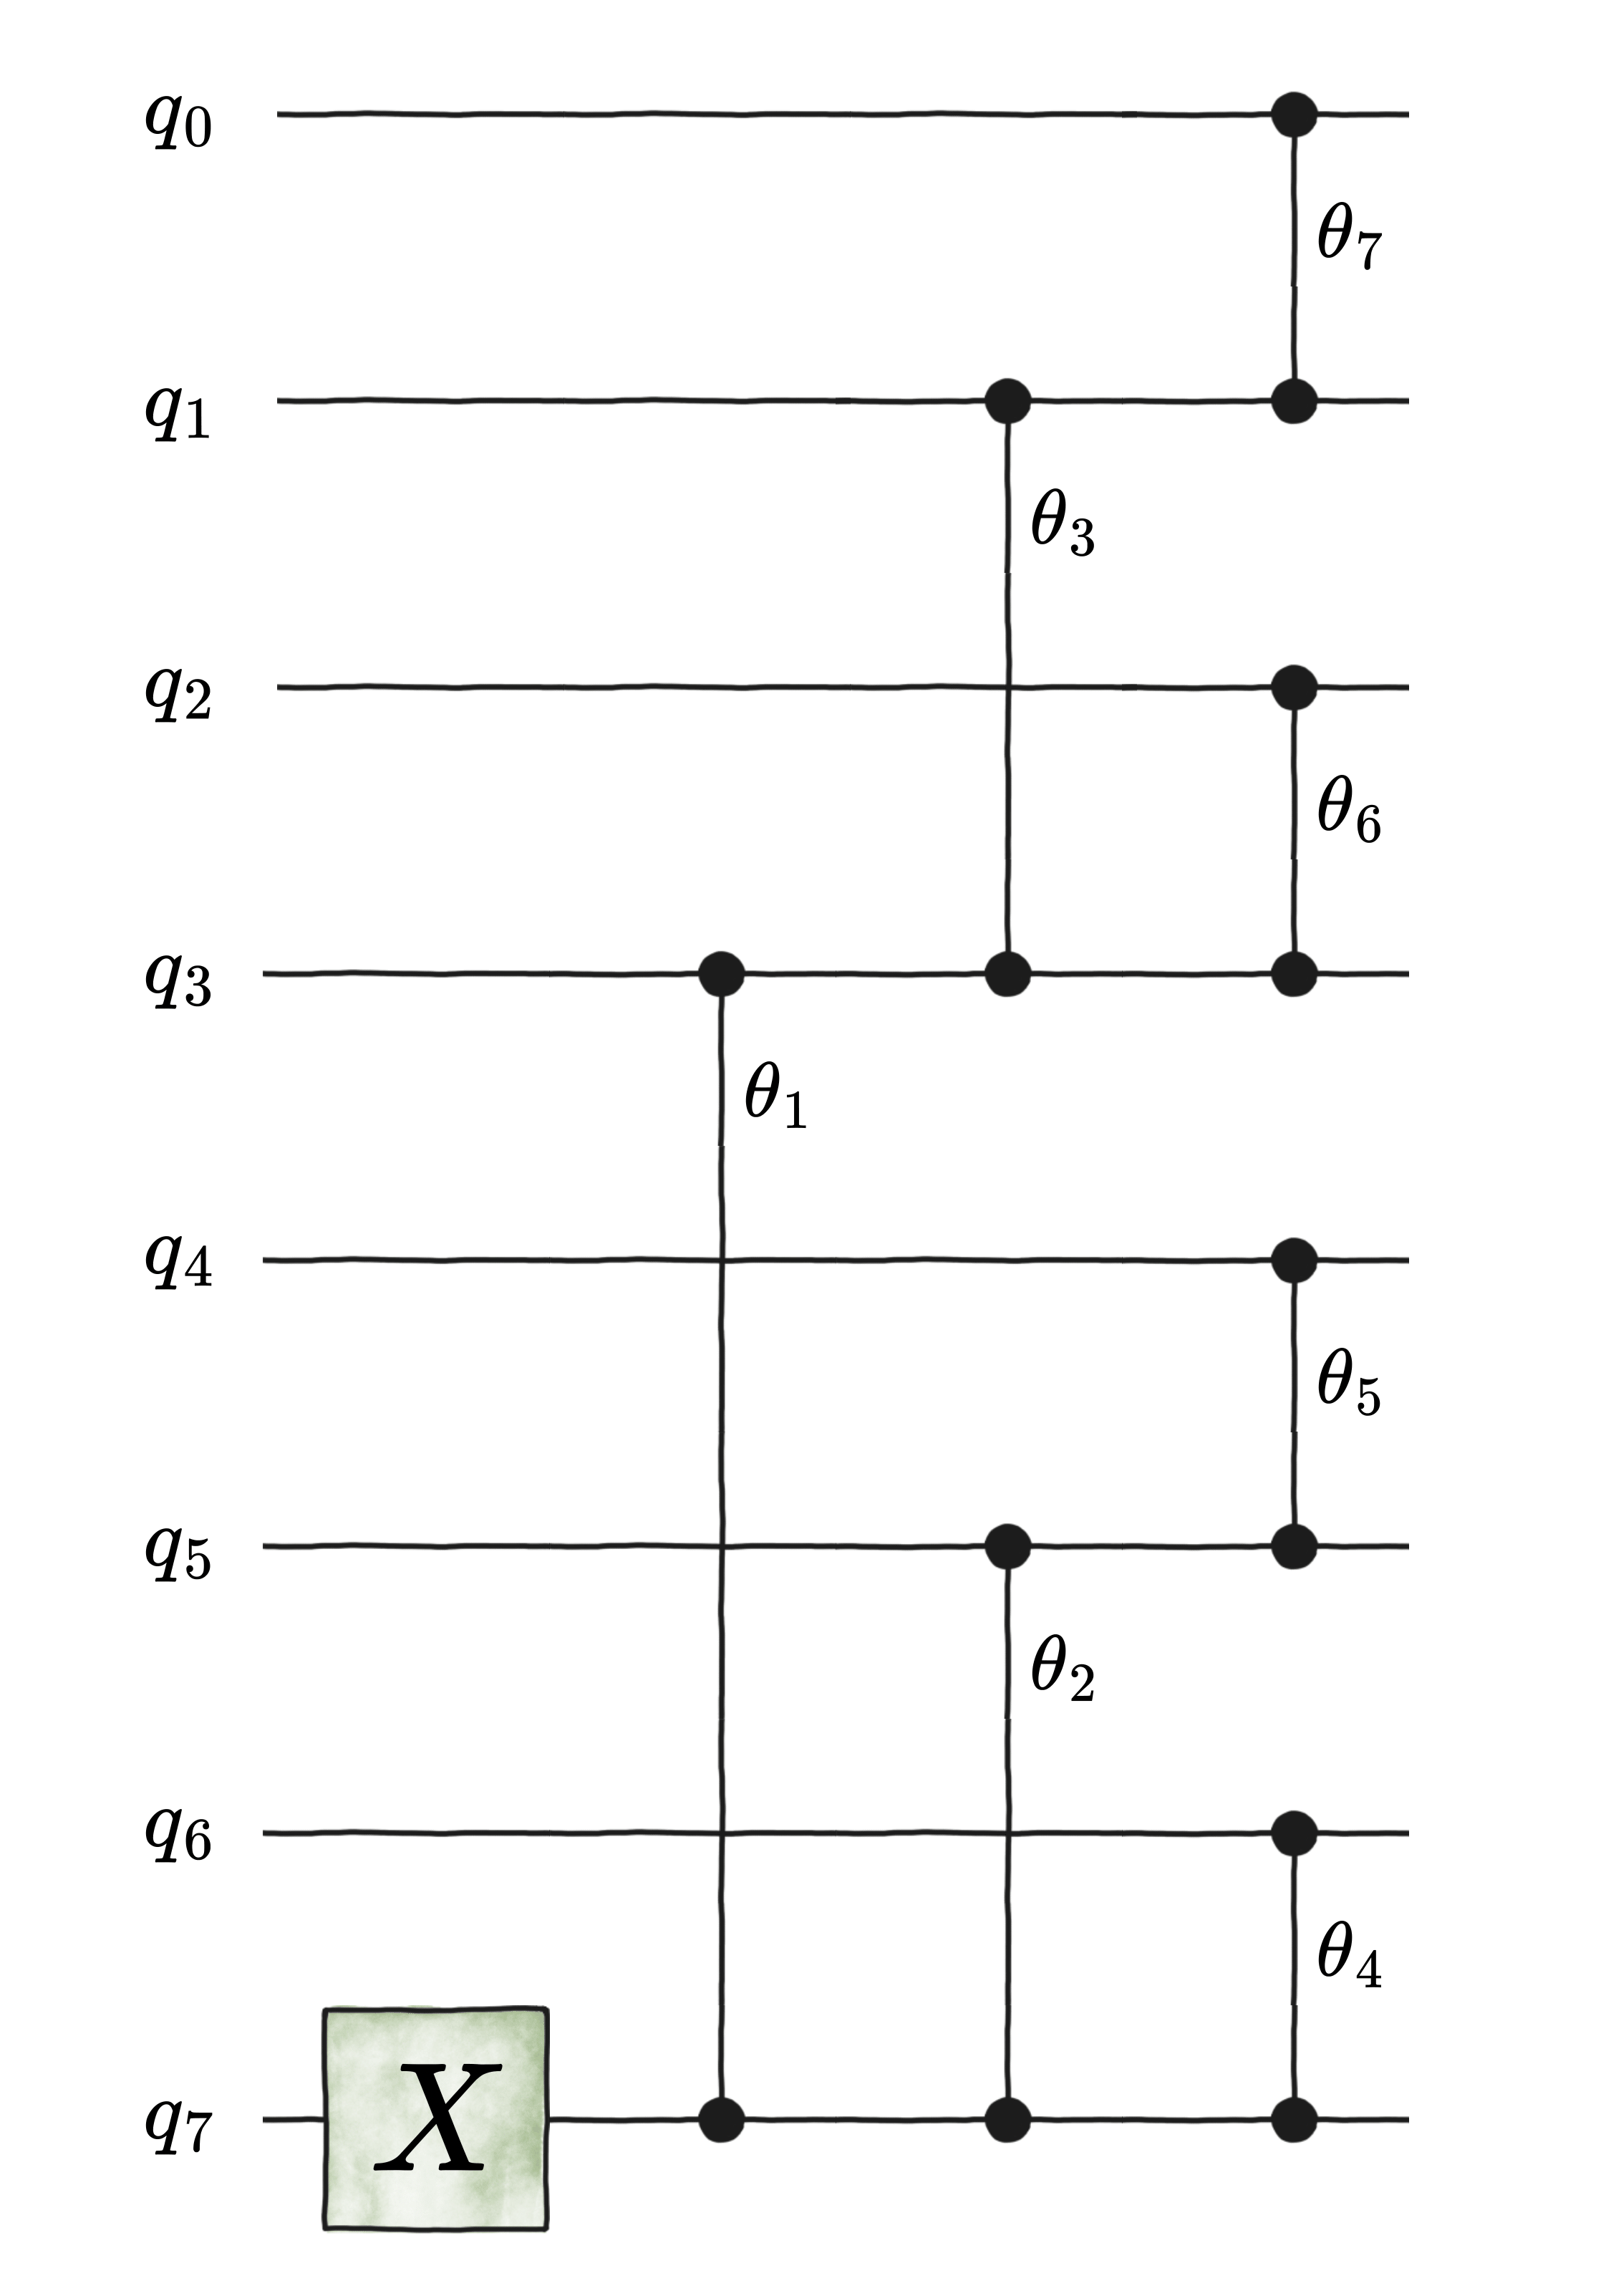
where the first gate is the qibo.gates.X
and the parametrized gates are the qibo.gates.RBS.
To know how the angles \(\{\theta_{k}\}_{[k]}\) are calculated for this architecture,
please refer to S. Johri et al., Nearest Centroid Classification on a Trapped Ion Quantum Computer,
arXiv:2012.04145v2 [quant-ph].
On the other hand, the same encoding could be performed using the so-called diagonal (also known as ladder) architecture below:
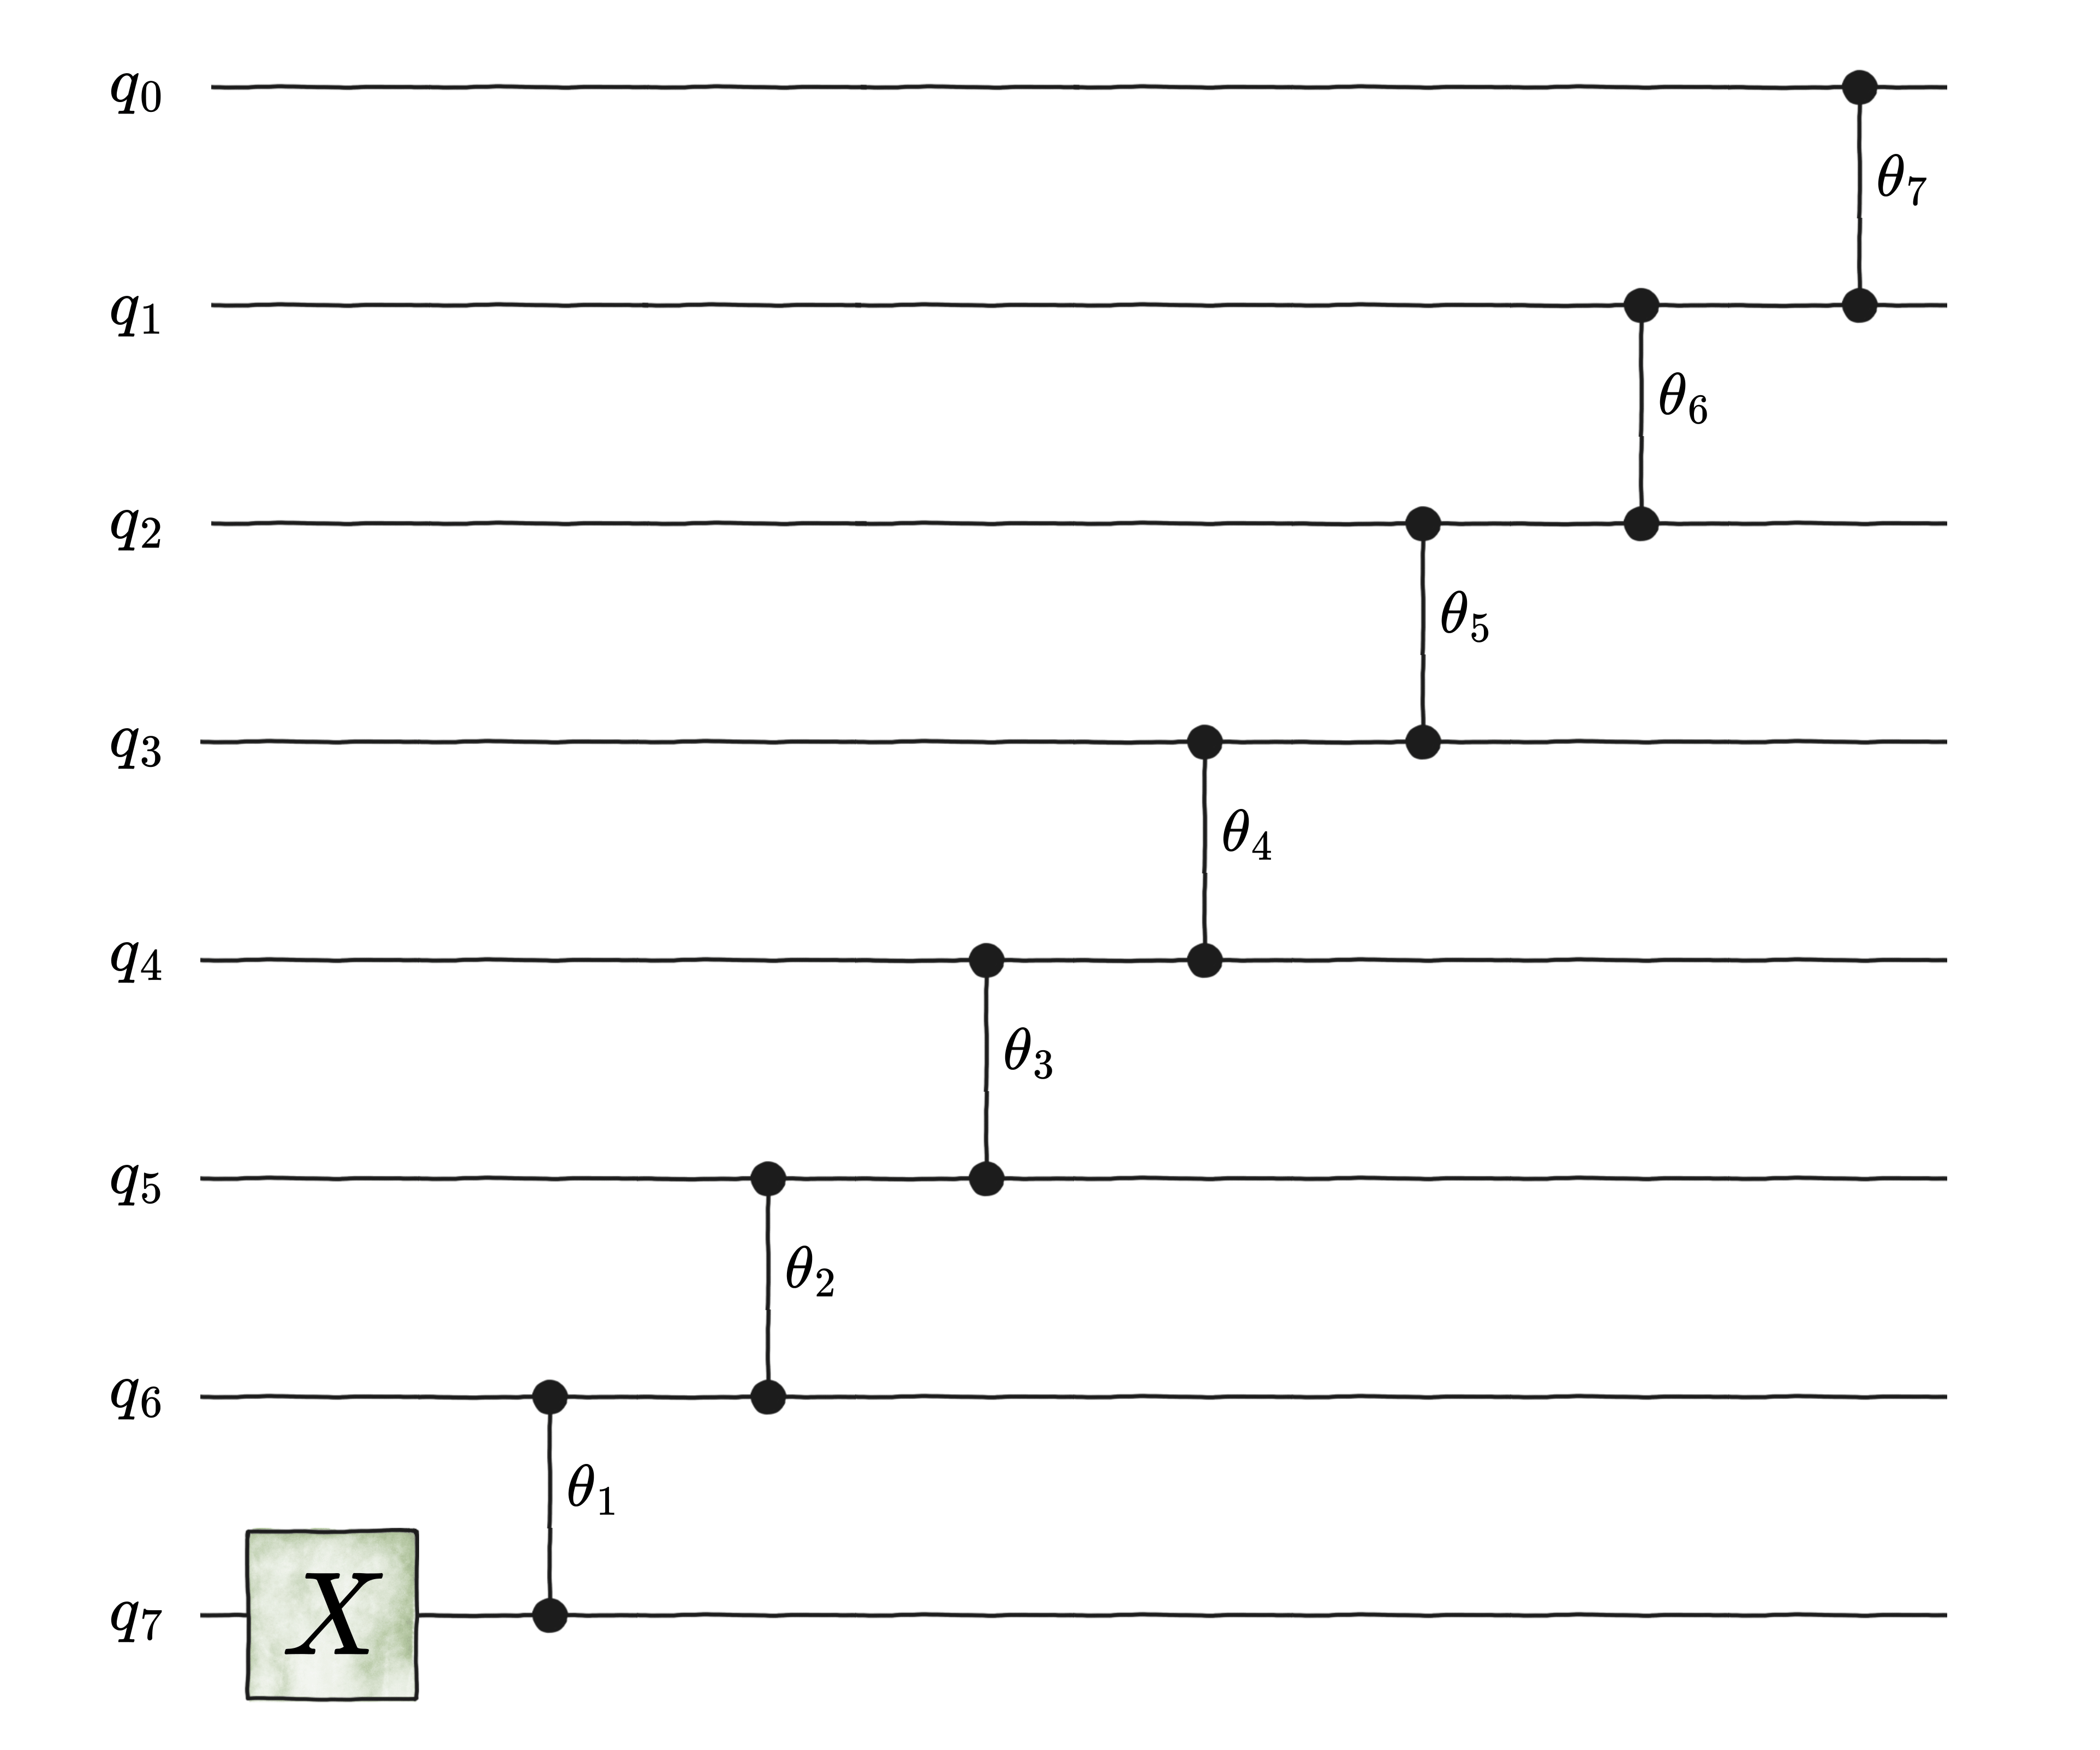
This architecture leads to a choice of angles based on spherical coordinates in a d-dimensional hypersphere.
- qibo.models.encodings.unary_encoder(nqubits, architecture='tree', data=None, backend=None, **kwargs)[source]#
Create circuit that performs the (deterministic) unary encoding of
data.- Parameters:
nqubits (int) – number of qubits in the system.
architecture (str, optional) – circuit architecture used for the unary loader. If
diagonal, uses a ladder-like structure. Iftree, uses a binary-tree-based structure. Defaults totree.data (ArrayLike) – \(1\)-dimensional array of data to be loaded. If
None, all phases in the returned circuit are set to \(0.0\).backend (
qibo.backends.abstract.Backend, optional) – backend to be used in the execution. IfNone, it uses the current backend. Defaults toNone.kwargs (dict, optional) – Additional arguments used to initialize a Circuit object. For details, see the documentation of
qibo.models.circuit.Circuit.
- Returns:
Circuit that loads
datain unary representation.- Return type:
Unary Encoder for Random Gaussian States#
Performs the same unary encoder as qibo.models.encodings.unary_encoder
using the tree architecture , with the difference being that now each entry
of the \(d\)-dimensional array is sampled from a Gaussian distribution
\(\mathcal{N}(0, 1)\).
- qibo.models.encodings.unary_encoder_random_gaussian(nqubits, architecture='tree', seed=None, backend=None, **kwargs)[source]#
Create a circuit that performs the unary encoding of a random Gaussian state.
At depth \(h\) of the tree architecture, the angles \(\theta_{k} \in [0, 2\pi]\) of the the gates \(RBS(\theta_{k})\) are sampled from the following probability density function:
\[p_{h}(\theta) = \frac{1}{2} \, \frac{\Gamma(2^{h-1})}{\Gamma^{2}(2^{h-2})} \, \left|\sin(\theta) \, \cos(\theta)\right|^{2^{h-1} - 1} \, ,\]where \(\Gamma(\cdot)\) is the Gamma function.
- Parameters:
nqubits (int) – number of qubits.
architecture (str, optional) – circuit architecture used for the unary loader. If
tree, uses a binary-tree-based structure. Defaults totree.seed (int or
numpy.random.Generator, optional) – Either a generator of random numbers or a fixed seed to initialize a generator. IfNone, initializes a generator with a random seed. Defaults toNone.backend (
qibo.backends.abstract.Backend, optional) – backend to be used in the execution. IfNone, it uses the current backend. Defaults toNone.kwargs (dict, optional) – Additional arguments used to initialize a Circuit object. For details, see the documentation of
qibo.models.circuit.Circuit.
- Returns:
Circuit that loads a random Gaussian array in unary representation.
- Return type:
References
1. A. Bouland, A. Dandapani, and A. Prakash, A quantum spectral method for simulating stochastic processes, with applications to Monte Carlo. arXiv:2303.06719v1 [quant-ph]
Up-to-Hamming-weight-\(k\) Encoder#
- qibo.models.encodings.up_to_k_hamming_weight_encoder(nqubits, up_to_k, data=None, complex_data=False, codewords=None, keep_antictrls=False, backend=None, **kwargs)[source]#
Create a circuit that encodes
datain the Hamming-weight-\(\leq k\) subspace ofnqubits.Let \(\mathbf{x}\) be a \(1\)-dimensional array of size
\[d = \sum_{l=0}^{k} \binom{n}{l},\]and define the union-Hamming-weight-subspace
\[B_{\le k} \equiv \left\{ \ket{b_j} : b_j \in \{0,1\}^{\otimes n}, \; |b_j| \le k \right\},\]i.e., the set of all computational basis states of \(n\) qubits whose bitstrings have Hamming weight less than or equal to \(k\). Equivalently,
\[B_{\le k} = \bigcup_{w=0}^{k} B_w,\]where \(B_w\) denotes the set of basis states of fixed Hamming weight \(w\).
An amplitude encoder in the basis \(B_{\le k}\) is an \(n\)-qubit parameterized quantum circuit \(\operatorname{Load}_{B_{\le k}}\) such that
\[\operatorname{Load}_{B_{\le k}}(\mathbf{x}) \, \ket{0}^{\otimes n} = \frac{1}{\|\mathbf{x}\|} \sum_{j=1}^{d} x_j \ket{b_j},\]where \(\{ \ket{b_j} \}_{j=1}^d\) is an enumeration of the elements of \(B_{\le k}\).
Resulting circuit parametrizes
datain eitherhypersphericalorhopfcoordinates in the \((2^{n} - 1)\)-unit sphere.- Parameters:
nqubits (int) – total number of qubits in the system.
up_to_k (int) – upper limit for the Hamming weight of the union-Hamming-weight-subspace in which the data to be loaded will be supported.
data (ArrayLike, optional) – \(1\)-dimensional array of length \(d = \sum_{l=0}^{k} \binom{n}{l}\) to be loaded in the amplitudes of a \(n\)-qubit quantum state. If
None, all phases of the returned circuit are set to \(0.0\). Defaults toNone.complex_data (bool, optional) – to be used when
data is None. IfTrue, returned circuit parametrizes complex-valued states. IfFalse, it parametrizes real-valued states. Ifdata is not None, then data type is inferred fromdata. Defaults toFalse.codewords (list, optional) – List of codewords used to encode the data in the given order. If
None, the codewords are set by the erhlich algorithm.keep_antictrls (bool, optional) – If
Trueand parametrization ishyperspherical, we don’t simplify the anti-controls when placing the RBS gates. For details, see [1].backend (
qibo.backends.abstract.Backend, optional) – backend to be used in the execution. IfNone, it uses the current backend. Defaults toNone.kwargs (dict, optional) – Additional arguments used to initialize a Circuit object. For details, see the documentation of
qibo.models.circuit.Circuit.
- Returns:
Circuit that loads
datain up-to-k encoding.- Return type:
References
1. R. M. S. Farias, T. O. Maciel, G. Camilo, R. Lin, S. Ramos-Calderer, and L. Aolita, Quantum encoder for fixed-Hamming-weight subspaces Phys. Rev. Applied 23, 044014 (2025).
Error Mitigation#
Qibo allows for mitigating noise in circuits via error mitigation methods. Unlike error correction, error mitigation does not aim to correct qubit errors, but rather it provides the means to estimate the noise-free expected value of an observable measured at the end of a noisy circuit.
Readout Mitigation#
A common kind of error happening in quantum circuits is readout error, i.e. the error in the measurement of the qubits at the end of the computation. In Qibo there are currently two methods implemented for mitigating readout errors, and both can be used as standalone functions or in combination with the other general mitigation methods by setting the paramter readout.
Response Matrix#
Given \(n\) qubits, all the possible \(2^n\) states are constructed via the application of the corresponding sequence of \(X\) gates \(X_0\otimes I_1\otimes\cdot\cdot\cdot\otimes X_{n-1}\). In the presence of readout errors, we will measure for each state \(i\) some noisy frequencies \(F_i^{noisy}\) different from the ideal ones \(F_i^{ideal}=\delta_{i,j}\).
The effect of the error is modeled by the response matrix composed of the noisy frequencies as columns \(M=\big(F_0^{noisy},...,F_{n-1}^{noisy}\big)\). We have indeed that:
and, therefore, the calibration matrix obtained as \(M_{\text{cal}}=M^{-1}\) can be used to recover the noise-free frequencies.
The calibration matrix \(M_{\text{cal}}\) lacks stochasticity, resulting in a ‘negative probability’ issue. The distributions that arise after applying \(M_{\text{cal}}\) are quasiprobabilities; the individual elements can be negative surpass 1, provided they sum to 1. It is posible to use Iterative Bayesian Unfolding (IBU) to preserve non-negativity. See Nachman et al for more details.
- qibo.models.error_mitigation.get_response_matrix(nqubits, qubit_map=None, noise_model=None, nshots=10000, backend=None)[source]#
Computes the response matrix for readout mitigation.
- Parameters:
nqubits (int) – Total number of qubits.
qubit_map (list, optional) – the qubit map. If None, a list of range of circuit’s qubits is used. Defaults to
None.noise_model (
qibo.noise.NoiseModel, optional) – noise model used for simulating noisy computation. This matrix can be used to mitigate the effect of qibo.noise.ReadoutError.nshots (int, optional) – number of shots. Defaults to \(10000\).
backend (
qibo.backends.abstract.Backend, optional) – backend to be used in the execution. IfNone, it uses the current backend. Defaults toNone.
- Returns:
the computed (nqubits, nqubits) response matrix for readout mitigation.
- Return type:
ArrayLike
- qibo.models.error_mitigation.iterative_bayesian_unfolding(probabilities, response_matrix, iterations=10)[source]#
Iterative Bayesian Unfolding (IBU) method for readout mitigation.
- Parameters:
probabilities (ArrayLike) – the input probabilities to be unfolded.
response_matrix (ArrayLike) – the response matrix.
iterations (int, optional) – the number of iterations to perform. Defaults to 10.
- Returns:
the unfolded probabilities.
- Return type:
ArrayLike
- Reference:
1. B. Nachman, M. Urbanek et al, Unfolding Quantum Computer Readout Noise. arXiv:1910.01969 [quant-ph]. 2. S. Srinivasan, B. Pokharel et al, Scalable Measurement Error Mitigation via Iterative Bayesian Unfolding. arXiv:2210.12284 [quant-ph].
- qibo.models.error_mitigation.apply_resp_mat_readout_mitigation(state, response_matrix, iterations=None)[source]#
Applies readout error mitigation to the given state using the provided response matrix.
- Parameters:
state (
qibo.measurements.CircuitResult) – the input state to be updated. This state should contain the frequencies that need to be mitigated.response_matrix (numpy.ndarray) – the response matrix for readout mitigation.
iterations (int, optional) – the number of iterations to use for the Iterative Bayesian Unfolding method. If
Nonethe ‘inverse’ method is used. Defaults toNone.
- Returns:
the input state with the updated (mitigated) frequencies.
- Return type:
qibo.measurements.CircuitResult
- qibo.models.error_mitigation.apply_randomized_readout_mitigation(circuit, noise_model=None, nshots=10000, ncircuits=10, qubit_map=None, seed=None, backend=None)[source]#
Readout mitigation method that transforms the bias in an expectation value into a measurable multiplicative factor.
This factor can be eliminated at the expense of increased sampling complexity for the observable.
- Parameters:
circuit (
qibo.models.Circuit) – input circuit.noise_model (
qibo.noise.NoiseModel, optional) – noise model used for simulating noisy computation. Defaults toNone.nshots (int, optional) – number of shots. Defaults to \(10000\).
ncircuits (int, optional) – number of randomized circuits. Each of them uses
int(nshots / ncircuits)shots. Defaults to 10.qubit_map (list, optional) – the qubit map. If
None, a list of range of circuit’s qubits is used. Defaults toNone.seed (int or
numpy.random.Generator, optional) – Either a generator of random numbers or a fixed seed to initialize a generator. IfNone, initializes a generator with a random seed. Default:None.backend (
qibo.backends.abstract.Backend, optional) – backend to be used in the execution. IfNone, it uses the current backend. Defaults toNone.
- Returns:
- the state of the input circuit with
mitigated frequencies.
- Return type:
qibo.measurements.CircuitResult
References
1. Ewout van den Berg, Zlatko K. Minev et al, Model-free readout-error mitigation for quantum expectation values. arXiv:2012.09738 [quant-ph].
- qibo.models.error_mitigation.get_expectation_val_with_readout_mitigation(circuit, observable, noise_model=None, nshots=10000, readout=None, qubit_map=None, seed=None, backend=None)[source]#
CDR: Applies readout error mitigation to the given circuit and observable.
- Parameters:
circuit (
qibo.models.Circuit) – input circuit.observable (
qibo.hamiltonians.Hamiltonian/:class:`qibo.hamiltonians.SymbolicHamiltonian) – The observable to be measured.noise_model (
qibo.models.noise.NoiseModel, optional) – the noise model to be applied. Defaults toNone.nshots (int, optional) – the number of shots for the circuit execution. Defaults to \(10^{4}\).
readout (dict, optional) –
a dictionary that may contain the following keys:
ncircuits: int, specifies the number of random circuits to use for the randomized method of readout error mitigation.
response_matrix: numpy.ndarray, used for applying a pre-computed response matrix for readout error mitigation.
ibu_iters: int, specifies the number of iterations for the iterative Bayesian unfolding method of readout error mitigation. If provided, the corresponding readout error mitigation method is used. Defaults to an empty
dict.
qubit_map (list, optional) – the qubit map. If None, a list of range of circuit’s qubits is used. Defaults to
None.seed (int or
numpy.random.Generator, optional) – Either a generator of random numbers or a fixed seed to initialize a generator. IfNone, initializes a generator with a random seed. Default:None.backend (qibo.backends.abstract.Backend, optional) – the backend to be used in the execution. If
None, it uses the global backend. Defaults toNone.
- Returns:
The mitigated expectation value of the observable.
- Return type:
Randomized readout mitigation#
This approach converts the effect of any noise map \(A\) into a single multiplication factor for each Pauli observable, that is, diagonalizes the measurement channel. The multiplication factor \(\lambda\) can be directly measured even without the quantum circuit. Dividing the measured value \(\langle O\rangle_{noisy}\) by these factor results in the mitigated Pauli expectation value \(\langle O\rangle_{ideal}\),
This process can be implemented with the aforementioned
qibo.models.error_mitigation.apply_randomized_readout_mitigation().
Zero Noise Extrapolation (ZNE)#
Given a noisy circuit \(C\) and an observable \(A\), Zero Noise Extrapolation (ZNE) consists in running \(n+1\) versions of the circuit with different noise levels \(\{c_j\}_{j=0..n}\) and, for each of them, measuring the expected value of the observable \(E_j=\langle A\rangle_j\).
Then, an estimate for the expected value of the observable in the noise-free condition is obtained as:
with \(\gamma_j\) satisfying:
This implementation of ZNE relies on the insertion of gate pairs (that resolve to the identity in the noise-free case) to realize the different noise levels \(\{c_j\}\), see He et al for more details. Hence, the canonical levels are mapped to the number of inserted pairs as \(c_j\rightarrow 2 c_j + 1\).
- qibo.models.error_mitigation.ZNE(circuit, observable, noise_levels, noise_model=None, nshots=10000, solve_for_gammas=False, global_unitary_folding=True, insertion_gate='CNOT', readout=None, qubit_map=None, seed=None, backend=None)[source]#
Runs the Zero Noise Extrapolation (ZNE) method for error mitigation.
The different noise levels are realized by the insertion of pairs of either
CNOTorRX(pi/2)gates that resolve to the identiy in the noise-free case.- Parameters:
circuit (
qibo.models.Circuit) – input circuit.observable (
qibo.hamiltonians.Hamiltonianorqibo.hamiltonians.SymbolicHamiltonian) – Observable to measure.noise_levels (ndarray) – Sequence of noise levels.
noise_model (
qibo.noise.NoiseModel, optional) – Noise model applied to simulate noisy computation.nshots (int, optional) – Number of shots. Defaults to \(10000\). If
None, the circuit is simulated without sampling: with statevector simulation if noise_model is not None and with density matrix simulation otherwise. Readout mitigation is not available with exact simulation.solve_for_gammas (bool, optional) – If
True, explicitly solve the equations to obtain thegammacoefficients. Default isFalse.global_unitary_folding (bool, optional) – If
True, noise is increased by global unitary folding. IfFalse, local unitary folding is used. Defaults toTrue.insertion_gate (str, optional) – gate to be folded in the local unitary folding. If
RX, the gate used is \(RX(\pi / 2)\). Otherwise, it is theqibo.gates.gates.CNOTgate.readout (dict, optional) –
a dictionary that may contain the following keys:
ncircuits: int, specifies the number of random circuits to use for the randomized method of readout error mitigation.
response_matrix:
ndarray, used for applying a pre-computed response matrix for readout error mitigation.ibu_iters: int, specifies the number of iterations for the iterative Bayesian unfolding method of readout error mitigation. If provided, the corresponding readout error mitigation method is used. Defaults to an empty
dict.
qubit_map (list, optional) – the qubit map. If None, a list of range of circuit’s qubits is used. Defaults to
None.seed (int or
numpy.random.Generator, optional) – Either a generator of random numbers or a fixed seed to initialize a generator. IfNone, initializes a generator with a random seed. Default:None.backend (
qibo.backends.abstract.Backend, optional) – backend to be used in the execution. IfNone, it uses the current backend. Defaults toNone.
- Returns:
Estimate of the expected value of
observablein the noise free condition.- Return type:
ArrayLike
- Reference:
1. K. Temme, S. Bravyi et al, Error mitigation for short-depth quantum circuits. Phys. Rev. Lett. 119, 180509 (2017).
- qibo.models.error_mitigation.get_gammas(noise_levels, analytical=True)[source]#
Standalone function to compute the ZNE coefficients given the noise levels.
- Parameters:
noise_levels (numpy.ndarray) – array containing the different noise levels. Note that in the CNOT insertion paradigm this corresponds to the number of CNOT pairs to be inserted. The canonical ZNE noise levels are obtained as
2 * c + 1.analytical (bool, optional) – if
True, computes the coeffients by solving the linear system. IfFalse, use the analytical solution valid for the CNOT insertion method. Default isTrue.
- Returns:
the computed coefficients.
- Return type:
numpy.ndarray
- qibo.models.error_mitigation.get_noisy_circuit(circuit, num_insertions, global_unitary_folding=True, insertion_gate=None)[source]#
Standalone function to generate the noisy circuit with the inverse gate pairs insertions.
- Parameters:
circuit (
qibo.models.circuit.Circuit) – circuit to modify.num_insertions (int) – number of insertion gate pairs / global unitary folds to add.
global_unitary_folding (bool) – If
True, noise is increased by global unitary folding. IfFalse, local unitary folding is used. Defaults toTrue.insertion_gate (str, optional) – gate to be folded in the local unitary folding. If
RX, the gate used is \(RX(\pi / 2)\). Otherwise, it is theCNOTgate.
- Returns:
circuit with the inserted gate pairs or with global folding.
- Return type:
qibo.models.Circuit
Clifford Data Regression (CDR)#
In the Clifford Data Regression (CDR) method, a set of \(n\) circuits \(S_n=\{C_i\}_{i=1,..,n}\) is generated starting from the original circuit \(C_0\) by replacing some of the non-Clifford gates with Clifford ones. Given an observable \(A\), all the circuits of \(S_n\) are both simulated to obtain the correspondent expected values of \(A\) in noise-free condition \(\{a_i^{exact}\}_{i=1,..,n}\), and run in noisy conditions to obtain the noisy expected values \(\{a_i^{noisy}\}_{i=1,..,n}\).
Finally a model \(f\) is trained to minimize the mean squared error:
and learn the mapping \(a^{noisy}\rightarrow a^{exact}\). The mitigated expected value of \(A\) at the end of \(C_0\) is then obtained simply with \(f(a_0^{noisy})\).
In this implementation the initial circuit is expected to be decomposed in the three Clifford gates \(RX(\frac{\pi}{2})\), \(CNOT\), \(X\) and in \(RZ(\theta)\) (which is Clifford only for \(\theta=\frac{n\pi}{2}\)). By default the set of Clifford gates used for substitution is \(\{RZ(0),RZ(\frac{\pi}{2}),RZ(\pi),RZ(\frac{3}{2}\pi)\}\). See Sopena et al for more details.
- qibo.models.error_mitigation.CDR(circuit, observable, noise_model, nshots=10000, model=<function <lambda>>, n_training_samples=100, full_output=False, readout=None, qubit_map=None, seed=None, backend=None)[source]#
Runs the Clifford Data Regression error mitigation method.
- Parameters:
circuit (
qibo.models.Circuit) – input circuit decomposed in the primitive gatesX,CNOT,RX(pi/2),RZ(theta).observable (
qibo.hamiltonians.Hamiltonian/:class:`qibo.hamiltonians.SymbolicHamiltonian) – observable to be measured.noise_model (
qibo.noise.NoiseModel) – noise model used for simulating noisy computation.nshots (int, optional) – Number of shots. Defaults to \(10000\). If None, the circuit is simulated without sampling: with statevector simulation if noise_model is not None and with density matrix simulation otherwise. Readout mitigation is not available with exact simulation.
model (callable, optional) – model used for fitting. This should be a callable function object
f(x, *params), taking as input the predictor variable and the parameters. Default is a simple linear modelf(x,a,b) := a*x + b.n_training_samples (int, optional) – number of training circuits to sample. Defaults to \(100\).
full_output (bool, optional) – if
True, this function returns additional information:val,optimal_params,train_val. Defaults toFalse.readout (dict, optional) –
a dictionary that may contain the following keys:
ncircuits: int, specifies the number of random circuits to use for the randomized method of readout error mitigation.
response_matrix: numpy.ndarray, used for applying a pre-computed response matrix for readout error mitigation.
ibu_iters: int, specifies the number of iterations for the iterative Bayesian unfolding method of readout error mitigation. If provided, the corresponding readout error mitigation method is used. Defaults to an empty
dict.
qubit_map (list, optional) – the qubit map. If None, a list of range of circuit’s qubits is used. Defaults to
None.seed (int or
numpy.random.Generator, optional) – Either a generator of random numbers or a fixed seed to initialize a generator. IfNone, initializes a generator with a random seed. Default:None.backend (
qibo.backends.abstract.Backend, optional) – backend to be used in the execution. IfNone, it uses the current backend. Defaults toNone.
- Returns:
Mitigated expectation value of observable. val (float): Noisy expectation value of observable. optimal_params (list): Optimal values for params. train_val (dict): Contains the noise-free and noisy expectation values obtained with the training circuits.
- Return type:
mit_val (float)
- Reference:
P. Czarnik, A. Arrasmith et al, Error mitigation with Clifford quantum-circuit data. arXiv:2005.10189 [quant-ph].
- qibo.models.error_mitigation.sample_training_circuit_cdr(circuit, replacement_gates=None, sigma=0.5, seed=None, backend=None)[source]#
Samples a training circuit for CDR by susbtituting some of the non-Clifford gates.
- Parameters:
circuit (
qibo.models.Circuit) – circuit to sample from, decomposed inRX(pi/2),X,CNOTandRZgates.replacement_gates (list, optional) – candidates for the substitution of the non-Clifford gates. The
listshould be composed bytuplesof the form (gates.XYZ,kwargs). For example, phase gates are used by default:list((RZ, {'theta':0}), (RZ, {'theta':pi/2}), (RZ, {'theta':pi}), (RZ, {'theta':3*pi/2})).sigma (float, optional) – standard devation of the Gaussian distribution used for sampling.
seed (int or
numpy.random.Generator, optional) – Either a generator of random numbers or a fixed seed to initialize a generator. IfNone, initializes a generator with a random seed. Default:None.backend (
qibo.backends.abstract.Backend, optional) – backend to be used in the execution. IfNone, it uses the current backend. Defaults toNone.
- Returns:
The sampled circuit.
- Return type:
qibo.models.Circuit
Variable Noise CDR (vnCDR)#
Variable Noise CDR (vnCDR) is an extension of the CDR method described above that factors in different noise levels as in ZNE. In detail, the set of circuits \(S_n=\{\mathbf{C}_i\}_{i=1,..,n}\) is still generated as in CDR, but for each \(\mathbf{C}_i\) we have \(k\) different versions of it with increased noise \(\mathbf{C}_i=C_i^0,C_i^1,...,C_i^{k-1}\).
Therefore, in this case we have a \(k\)-dimensional predictor variable \(\mathbf{a}_i^{noisy}=\big(a_i^0, a_i^1,..,a_i^{k-1}\big)^{noisy}\) for the same noise-free targets \(a_i^{exact}\), and we want to learn the mapping:
via minimizing the same mean squared error:
In particular, the default choice is to take \(f(\mathbf{x}):=\Gamma\cdot \mathbf{x}\;\), with \(\Gamma=\text{diag}(\gamma_0,\gamma_1,...,\gamma_{k-1})\;\), that corresponds to the ZNE calculation for the estimate of the expected value.
Here, as in the implementation of the CDR above, the circuit is supposed to be decomposed in the set of primitive gates \({RX(\frac{\pi}{2}),CNOT,X,RZ(\theta)}\). See Sopena et al for all the details.
- qibo.models.error_mitigation.vnCDR(circuit, observable, noise_levels, noise_model, nshots=10000, model=None, n_training_samples=100, insertion_gate='CNOT', full_output=False, readout=None, qubit_map=None, seed=None, backend=None)[source]#
Runs the variable-noise Clifford Data Regression error mitigation method.
- Parameters:
circuit (
qibo.models.Circuit) – input circuit decomposed in the primitive gatesX,CNOT,RX(pi/2),RZ(theta).observable (
qibo.hamiltonians.Hamiltonianorqibo.hamiltonians.SymbolicHamiltonian) – observable to be measured.noise_levels (ArrayLike) – sequence of noise levels.
noise_model (
qibo.noise.NoiseModel) – noise model used for simulating noisy computation.nshots (int, optional) – Number of shots. Defaults to \(10000\). If None, the circuit is simulated without sampling: with statevector simulation if noise_model is not None and with density matrix simulation otherwise. Readout mitigation is not available with exact simulation.
model (callable, optional) – model used for fitting. This should be a callable function object
f(x, *params), taking as input the predictor variable and the parameters. Default is a simple linear modelf(x,a,b) := a*x + b.n_training_samples (int, optional) – number of training circuits to sample.
insertion_gate (str, optional) – gate to be used in the insertion. If
"RX", the gate used is \(RX(\pi / 2)\). Default is"CNOT".full_output (bool, optional) – if
True, this function returns additional information:val,optimal_params,train_val. Defaults toFalse.readout (dict, optional) –
a dictionary that may contain the following keys:
ncircuits: int, specifies the number of random circuits to use for the randomized method of readout error mitigation.
response_matrix: numpy.ndarray, used for applying a pre-computed response matrix for readout error mitigation.
ibu_iters: int, specifies the number of iterations for the iterative Bayesian unfolding method of readout error mitigation. If provided, the corresponding readout error mitigation method is used. Defaults to empty
dict.
qubit_map (list, optional) – the qubit map. If
None, a list of range of circuit’s qubits is used. Defaults toNone.seed (int or
numpy.random.Generator, optional) – Either a generator of random numbers or a fixed seed to initialize a generator. IfNone, initializes a generator with a random seed. Default:None.backend (
qibo.backends.abstract.Backend, optional) – backend to be used in the execution. IfNone, it uses the current backend. Defaults toNone.
- Returns:
Mitigated expectation value of observable. val (list): Expectation value of observable with increased noise levels. optimal_params (list): Optimal values for params. train_val (dict): Contains the noise-free and noisy expectation values obtained with the training circuits.
- Return type:
mit_val (float)
- Reference:
A. Lowe, MH. Gordon et al, Unified approach to data-driven quantum error mitigation. arXiv:2011.01157 [quant-ph].
Importance Clifford Sampling (ICS)#
In the Importance Clifford Sampling (ICS) method, a set of \(n\) circuits \(S_n=\{C_i\}_{i=1,..,n}\) that stabilizes a given Pauli observable is generated starting from the original circuit \(C_0\) by replacing all the non-Clifford gates with Clifford ones. Given an observable \(A\), all the circuits of \(S_n\) are both simulated to obtain the correspondent expected values of \(A\) in noise-free condition \(\{a_i^{exact}\}_{i=1,..,n}\), and run in noisy conditions to obtain the noisy expected values \(\{a_i^{noisy}\}_{i=1,..,n}\).
Finally, a theoretically inspired model \(f\) is learned using the training data.
The mitigated expected value of \(A\) at the end of \(C_0\) is then obtained simply with \(f(a_0^{noisy})\).
In this implementation the initial circuit is expected to be decomposed in the three Clifford gates \(RX(\frac{\pi}{2})\), \(CNOT\), \(X\) and in \(RZ(\theta)\) (which is Clifford only for \(\theta=\frac{n\pi}{2}\)). By default the set of Clifford gates used for substitution is \(\{RZ(0),RZ(\frac{\pi}{2}),RZ(\pi),RZ(\frac{3}{2}\pi)\}\). See Sopena et al for more details.
- qibo.models.error_mitigation.ICS(circuit, observable, readout=None, qubit_map=None, noise_model=None, nshots=10000, n_training_samples=10, full_output=False, seed=None, backend=None)[source]#
Computes the Important Clifford Sampling method.
- Parameters:
circuit (
qibo.models.Circuit) – input circuit.observable (
qibo.hamiltonians.Hamiltonianorqibo.hamiltonians.SymbolicHamiltonian) – the observable to be measured.readout (dict, optional) –
a dictionary that may contain the following keys:
ncircuits: int, specifies the number of random circuits to use for the randomized method of readout error mitigation.
response_matrix: numpy.ndarray, used for applying a pre-computed response matrix for readout error mitigation.
ibu_iters: int, specifies the number of iterations for the iterative Bayesian unfolding method of readout error mitigation. If provided, the corresponding readout error mitigation method is used. Defaults to an empty
dict.
qubit_map (list, optional) – the qubit map. If
None, a list of range of circuit’s qubits is used. Defaults toNone.noise_model (
qibo.models.noise.NoiseModel, optional) – the noise model to be applied. Defaults toNone.nshots (int, optional) – Number of shots. Defaults to \(10000\). If None, the circuit is simulated without sampling: with statevector simulation if noise_model is not None and with density matrix simulation otherwise. Readout mitigation is not available with exact simulation.
n_training_samples (int, optional) – the number of training samples. Defaults to 10.
full_output (bool, optional) – if
True, this function returns additional information:val,optimal_params,train_val. Defaults toFalse.seed (int or
numpy.random.Generator, optional) – Either a generator of random numbers or a fixed seed to initialize a generator. IfNone, initializes a generator with a random seed. Default:None.backend (qibo.backends.abstract.Backend, optional) – the backend to be used in the execution. If
None, it uses the global backend. Defaults toNone.
- Returns:
the mitigated expectated value. mitigated_expectation_std (float): the standard deviation of the mitigated expectated value. dep_param (float): the depolarizing parameter. dep_param_std (float): the standard deviation of the depolarizing parameter. lambda_list (list): the list of the depolarizing parameters. data (dict): the data dictionary containing the noise-free and noisy expectation values obtained with the training circuits.
- Return type:
mitigated_expectation (float)
- Reference:
1. Dayue Qin, Yanzhu Chen et al, Error statistics and scalability of quantum error mitigation formulas, npj Quantum Inf 9, 35 (2023).
- qibo.models.error_mitigation.sample_clifford_training_circuit(circuit, seed=None, backend=None)[source]#
Samples a training circuit for CDR by susbtituting all the non-Clifford gates.
- Parameters:
circuit (
qibo.models.Circuit) – circuit to sample from.seed (int or
numpy.random.Generator, optional) – Either a generator of random numbers or a fixed seed to initialize a generator. IfNone, initializes a generator with a random seed. Default:None.backend (
qibo.backends.abstract.Backend, optional) – backend to be used in the execution. IfNone, it uses the current backend. Defaults toNone.
- Returns:
the sampled circuit.
- Return type:
qibo.models.Circuit